 手游源码
点击放大
项目说明
RLCard: A Toolkit for Reinforcement Learning in Card Games
<img width="500" src=" alt="Logo" />
![Testing]()
![PyPI ]()
![Co Status]()
![Downloads]()
![Downloads]()
![License: MIT]()
中文文档
RLCard is a toolkit for Reinforcement Learning (RL) in card games. It supports multiple card en with easy-to-use interfaces for implementing reinforcement learning and searching algorithms. The goal of RLCard is to bridge reinforcement learning and imperfect information games. RLCard is de by DATA Lab at Rice and Texas A&M Uni, and community contributors.
* Official Website:
* Tutorial in Jupyter Notebook:
* Paper:
* Video: YouTube
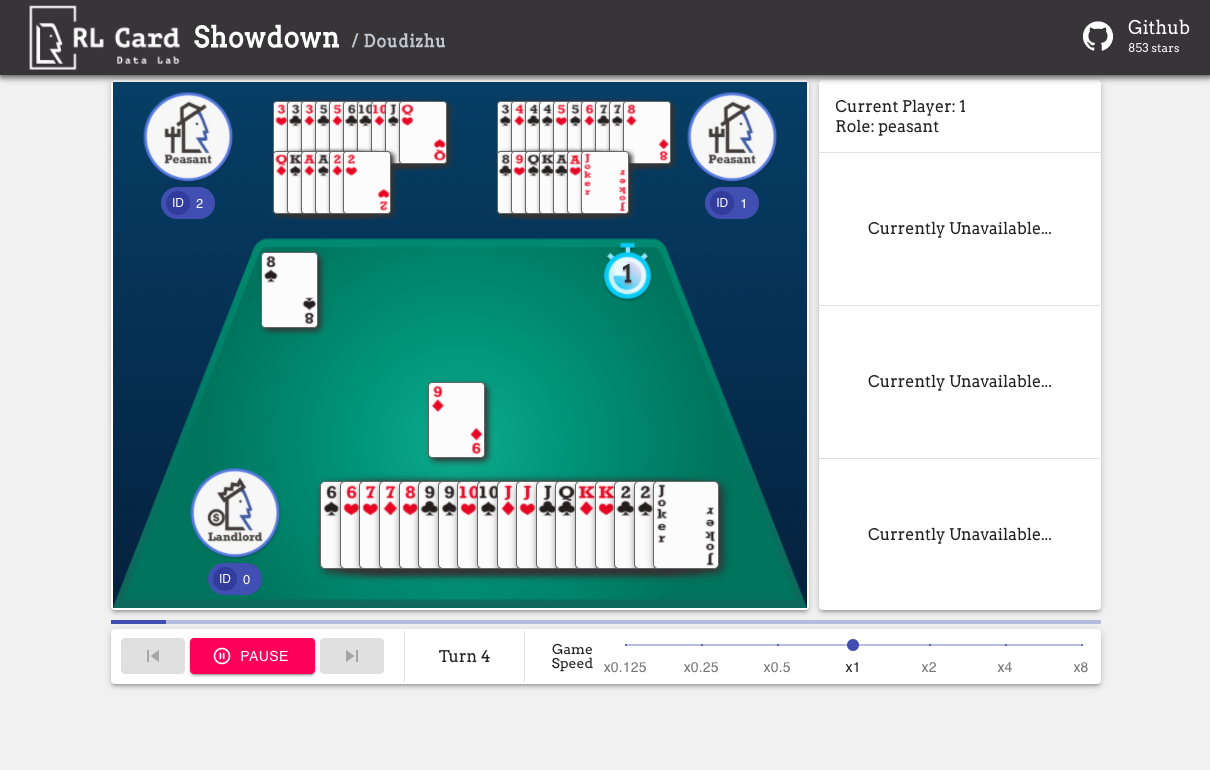
* GUI: RLCard-Showdown
* Dou Dizhu Demo: Demo
* Resources: Awesome-Game-AI
* Related Project: DouZero Project
* Zhihu:
* Miscellaneous Resources:
* Check out our open-sourced Large Time Series Model (LTSM)!
* Have you heard of data-centric AI? Please check out our data-centric AI survey and awesome data-centric AI resources!
Community:
* Slack: Discuss in our #rlcard-project slack channel.
* QQ Group: Join our QQ group to discuss. Password: rlcardqqgroup
* Group 1: 665647450
* Group 2: 117349516
News:
* We ha the tutorials in Jupyter Notebook to help you walk through RLCard! Please check RLCard Tutorial.
* All the algorithms can suppport PettingZoo now. Please check here. Thanks the contribtuion from Yifei Cheng.
* Please follow DouZero, a strong Dou Dizhu AI and the ICML 2021 paper. An online demo is a here. The algorithm is also integrated in RLCard. See Training DMC on Dou Dizhu.
* Our package is used in PettingZoo. Please check it out!
* We ha RLCard-Showdown, 界面 demo for RLCard. Please check out here!
* Jupyter Notebook tutorial a! We add some examples in R to call Python interfaces of RLCard with reticulate. See here
* Thanks for the contribution of for supporting different number of players in Blackjack. We call for contributions for gradually making the games more configurable. See here for more details.
* Thanks for the contribution of for the Blackjack and Limit Hold'em human interface.
* Now RLCard supports en local seeding and multiprocessing. Thanks for the testing scripts provided by .
* Human interface of NoLimit Holdem a. The action space of NoLimit Holdem has been abstracted. Thanks for the contribution of -.
* New 游戏 Gin Rummy and human 界面 a. Thanks for the contribution of .
* PyTorch implementation a. Thanks for the contribution of .
Contributors
The following games are mainly de and maintained by community contributors. Thank you!
* Gin Rummy:
* Bridge:
Thank all the contributors!
<a href=" src=" width="40px" alt="daochenzha" /></a>
<a href=" src=" width="40px" alt="hsywhu" /></a>
<a href=" src=" width="40px" alt="CaoYuanpu" /></a>
<a href=" src=" width="40px" alt="billh0420" /></a>
<a href=" src=" width="40px" alt="ruzhwei" /></a>
<a href=" src=" width="40px" alt="adrianpgob" /></a>
<a href=" src=" width="40px" alt="Zhigal" /></a>
<a href=" src=" width="40px" alt="aypee19" /></a>
<a href=" src=" width="40px" alt="Clarit7" /></a>
<a href=" src=" width="40px" alt="lhenry15" /></a>
<a href=" src=" width="40px" alt="ismael-elatifi" /></a>
<a href=" src=" width="40px" alt="mjudell" /></a>
<a href=" src=" width="40px" alt="jkterry1" /></a>
<a href=" src=" width="40px" alt="kaanozdogru" /></a>
<a href=" src=" width="40px" alt="junyuGuo" /></a>
<br />
<a href=" src=" width="40px" alt="Xixo99" /></a>
<a href=" src=" width="40px" alt="rodrigodelazcano" /></a>
<a href=" src=" width="40px" alt="Michael1015198808" /></a>
<a href=" src=" width="40px" alt="mia1996" /></a>
<a href=" src=" width="40px" alt="kaiks" /></a>
<a href=" src=" width="40px" alt="claude9493" /></a>
<a href=" src=" width="40px" alt="SonSang" /></a>
<a href=" src=" width="40px" alt="rishabh" /></a>
<a href=" src=" width="40px" alt="aetheryang" /></a>
<a href=" src=" width="40px" alt="rxng8" /></a>
<a href=" src=" width="40px" alt="nondecidibile" /></a>
<a href=" src=" width="40px" alt="benblack769" /></a>
<a href=" src=" width="40px" alt="zhengsx" /></a>
<a href=" src=" width="40px" alt="andrewnc" /></a>
Cite this work
If you find this repo useful, you may cite:
Zha, Daochen, et al. "RLCard: A Platform for Reinforcement Learning in Card Games." IJCAI. 2020.
Installation
Make sure that you have Python 3.6+ and pip installed. We recommend installing the stable of
rlcard with pip:The default installation will only include the card en. To use PyTorch implementation of the training algorithms, run
If you are in China and the abo is too slow, you can use the mirror provided by Tsinghua Uni:
Alternatively, you can clone the latest with (if you are in China and Github is slow, you can use the mirror in Gitee):
or only clone one branch to make it faster:
Then install with
We also provide conda installation method:
Conda installation only provides the card en, you need to manually install Pytorch on your demands.
Examples
A short example is as below.
RLCard can be flexibly connected to algorithms. See the following examples:
* Playing with random agents
* Deep-Q learning on Blackjack
* Training CFR (chance sampling) on Leduc Hold'em
* Having fun with pretrained Leduc model
* Training DMC on Dou Dizhu
* E Agents
* Training Agents on PettingZoo
Demo
Run
examples/human/leduc_holdem_human.py to play with the pre-trained Leduc Hold'em model. Leduc Hold'em is a simplified of Texas Hold'em. Rules can be found here.We also provide a 界面 for easy debugging. Please check here. Some demos:
!doudizhu-replay
!leduc-replay
A En
We provide a complexity estimation for the games on several aspects. InfoSet Number: the number of information sets; InfoSet Size: the a number of states in a single information set; Action Size: the size of the action space. Name: the name that should be passed to
rlcard.make to create the 游戏 en. We also provide the link to the documentation and the random example.| 游戏 | InfoSet Number | InfoSet Size | Action Size | Name | Usage |
| :--------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------: | :-------------: | :---------------: | :---------: | :-------------: | :-----------------------------------------------------------------------------------------: |
| Blackjack (wiki, baike) | 10^3 | 10^1 | 10^0 | blackjack | doc, example |
| Leduc Hold’em (paper) | 10^2 | 10^2 | 10^0 | leduc-holdem | doc, example |
| Limit Texas Hold'em (wiki, baike) | 10^14 | 10^3 | 10^0 | limit-holdem | doc, example |
| Dou Dizhu (wiki, baike) | 10^53 ~ 10^83 | 10^23 | 10^4 | doudizhu | doc, example |
| 麻将 (wiki, baike) | 10^121 | 10^48 | 10^2 | mahjong | doc, example |
| No-limit Texas Hold'em (wiki, baike) | 10^162 | 10^3 | 10^4 | no-limit-holdem | doc, example |
| UNO (wiki), baike) | 10^163 | 10^10 | 10^1 | uno | doc, example |
| Gin Rummy (wiki, baike) | 10^52 | - | - | gin-rummy | doc, example |
| Bridge (wiki, baike) | | - | - | bridge | doc, example |
Supported Algorithms
| Algorithm | example | reference |
| :--------------------------------------: | :-----------------------------------------: | :------------------------------------------------------------------------------------------------------: |
| Deep Monte-Carlo (DMC) | examples/run\_dmc.py | [[paper]]() |
| Deep Q-Learning (DQN) | examples/run\_rl.py | [[paper]]() |
| Neural Fictitious Self-Play (NFSP) | examples/run\_rl.py | [[paper]]() |
| Counterfactual Regret Minimization (CFR) | examples/run\_cfr.py | [[paper]]() |
Pre-trained and Rule-based Models
We provide a model zoo to serve as the baselines.
| Model | Explanation |
| :--------------------------------------: | :------------------------------------------------------: |
| leduc-holdem-cfr | Pre-trained CFR (chance sampling) model on Leduc Hold'em |
| leduc-holdem-rule-v1 | Rule-based model for Leduc Hold'em, v1 |
| leduc-holdem-rule-v2 | Rule-based model for Leduc Hold'em, v2 |
| uno-rule-v1 | Rule-based model for UNO, v1 |
| limit-holdem-rule-v1 | Rule-based model for Limit Texas Hold'em, v1 |
| 斗地主-rule-v1 | Rule-based model for Dou Dizhu, v1 |
| gin-rummy-no | Gin Rummy novice rule model |
API Cheat Sheet
How to create an en
You can use the the following interface to make an en. You may optionally specify some configurations with a dictionary.
* en.make(env_id, config={}): Make an en.
env_id is a string of a en; config is a dictionary that specifies some en configurations, which are as follows.*
seed: Default None. Set a en local random seed for reproducing the results.*
allow_step_back: Default False. True if allowing step_back function to traverse backward in the tree.* 游戏 specific configurations: These fields start with
game_. Currently, we only support game_num_players in Blackjack, .Once the en is made, we can access some information of the 游戏.
* en: The number of actions.
* en: The number of players.
* en: The shape of the state space of the obser.
* en: The shape of the action features (Dou Dizhu's action can encoded as features)
What is state in RLCard
State is a Python dictionary. It consists of obser
state['obs'], legal actions state['legal_actions'], raw obser state['raw_obs'] and raw legal actions state['raw_legal_actions'].Basic interfaces
The following interfaces provide a basic usage. It is easy to use but it has assumtions on the agent. The agent must follow agent template.
* en(agents):
agents is a list of Agent object. The length of the list should be equal to the number of the players in the 游戏.* env.run(is_training=False): Run a complete 游戏 and return trajectories and payoffs. The function can be used after the
set_agents is called. If is_training is True, it will use step function in the agent to play the 游戏. If is_training is False, e will be called instead.Ad interfaces
For ad usage, the following interfaces allow flexible operations on the 游戏 tree. These interfaces do not make any assumtions on the agent.
* en(): Initialize a 游戏. Return the state and the first player ID.
* env.step(action, raw_action=False): Take one step in the en.
action can be raw action or integer; raw_action should be True if the action is raw action (string).* en(): A only when
allow_step_back is True. Take one step backward. This can be used for algorithms that operate on the 游戏 tree, such as CFR (chance sampling).* en(): Return
True if the current 游戏 is over. Otherewise, return False.* en(): Return the Player ID of the current player.
* en(player_id): Return the state that corresponds to
player_id.* en(): In the end of the 游戏, return a list of payoffs for all the players.
* enn(): (Currently only support some of the games) Obtain the perfect information at the current state.
Library Structure
The purposes of the main modules are listed as below:
* /examples: Examples of using RLCard.
* /docs: Documentation of RLCard.
* /tests: Testing scripts for RLCard.
* /rlcard/agents: Reinforcement learning algorithms and human agents.
* /rlcard/envs: En wrappers (state representation, action encoding etc.)
* /rlcard/games: game engines.
* /rlcard/models: Model zoo including pre-trained models and rule models.
More Documents
For more documentation, please refer to the Documents for general introductions. API documents are a at our website.
Contributing
Contribution to this project is greatly appreciated! Please create an issue for feedbacks/bugs. If you want to contribute codes, please refer to Contributing Guide. If you have any questions, please contact Daochen Zha with .
Acknowledgements
We would like to thank JJ World 网络 Technology Co.,LTD for the generous support and all the contributions from the community contributors.
技术栈
开发语言:Python
项目类型:卡牌游戏强化学习 AI(斗地主/德州等)
Star 数:3570
功能特点
这是一套卡牌游戏强化学习 AI(斗地主/德州等),代码结构清晰,适合开发者学习游戏的客户端渲染、服务端逻辑、场景管理与资源加载。项目涵盖了游戏的核心玩法、界面交互、地图与角色系统等模块,对理解游戏开发的完整流程具有较高的参考价值。
从技术实现角度看,游戏项目的难点在于:游戏循环与状态管理、资源加载与渲染优化、客户端与服务端的协议同步、以及多平台适配。本项目在这些方面提供了可运行的实现,开发者可以在此基础上进行二次开发或学习研究。
部署说明
1. 下载源码压缩包,解压到本地开发环境。
2. 根据项目类型准备对应的运行环境(Node.js / Go / C# / Unity / Godot 等)。
3. 按照 README 中的步骤配置依赖、数据库和配置文件。
4. 先启动服务端,再运行客户端,即可进入游戏进行测试。
注意:本项目仅供学习研究使用,请勿用于商业或非法用途。
学习价值
对于想进入游戏开发领域的开发者来说,这套源码是一个很好的入门参考。通过阅读代码,可以学习到游戏的核心玩法实现、场景与资源管理、网络协议设计、以及渲染优化等关键技术点。
同时,项目中的代码组织方式和模块划分,也展示了游戏项目在工程化方面的实践经验,值得开发者深入研究和借鉴。理解一个完整游戏项目的架构,对后续开发其他类型游戏也很有帮助。
免责声明
本资源来源于开源社区,仅供学习研究和技术交流使用,请勿用于任何商业或违法违规用途。使用本项目产生的一切后果由使用者自行承担。若涉及第三方权益,请联系删除。
| 资源标题 | rlcard - 卡牌游戏强化学习 AI(斗地主/德州等) |
| 所属分类 | 手游源码 |
| 发布作者 | admin |
| 发布时间 | 2026-10-05 21:10:59 |
| 下载权限 | 免费下载 |
| 附件数量 | 2 个下载链接 |
| 浏览次数 | 488 |
| 讨论数量 | 0 |
| 主题状态 | 正常讨论中 |