 黑客技术
点击放大
DeepLearningFlappyBird - Flappy Bird hack using Deep Reinforcement Learning
项目说明
Using Deep Q-网络 to Learn How To Play Flappy Bird
<img src="./images/flappy_bird_demp.gif" width="250">
7 mins : DQN for flappy bird
O
This project follows the description of the Deep Q Learning algorithm described in Playing Atari with Deep Reinforcement Learning [2] and shows that this learning algorithm can be further generalized to the notorious Flappy Bird.
Installation Dependencies:
* Python 2.7 or 3
* TensorFlow 0.7
* pygame
* OpenC
How to Run?
What is Deep Q-Network?
It is a con neural 网络, trained with a of Q-learning, whose input is raw pixels and whose output is a value function estimating future rewards.
For those who are interested in deep reinforcement learning, I highly recommend to read the following post:
Demystifying Deep Reinforcement Learning
Deep Q-Network Algorithm
The pseudo-代码 for the Deep Q Learning algorithm, as given in [1], can be found below:
Experiments
#### En
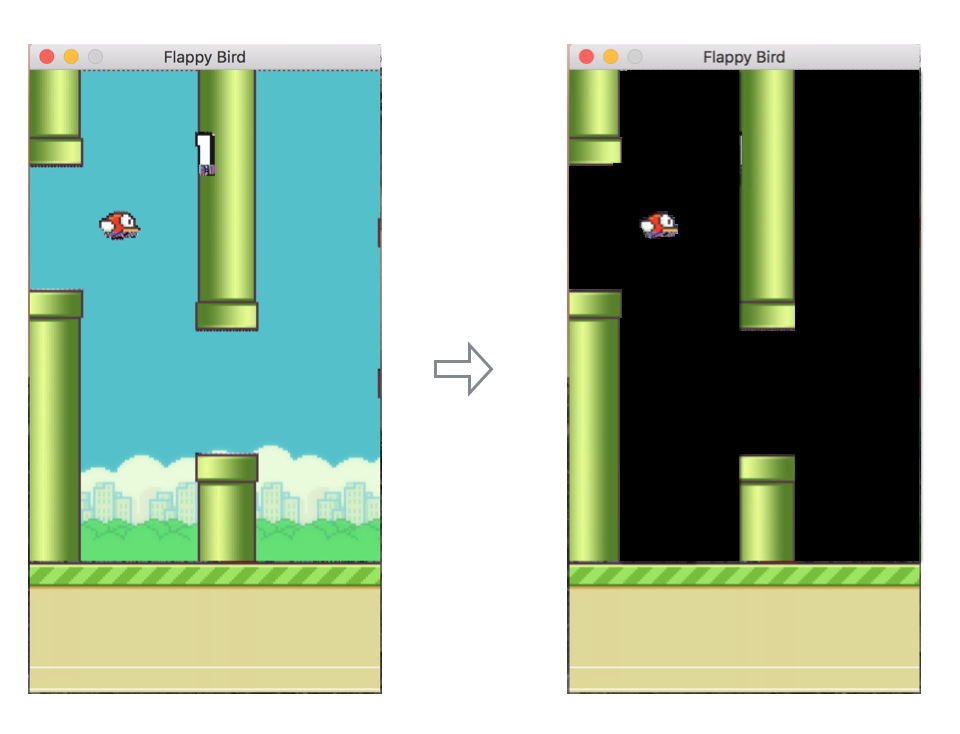
Since deep Q-网络 is trained on the raw pixel observed from the 游戏 screen at each time step, [3] finds that remove the background appeared in the original 游戏 can make it converge faster. This process can be as the following figure:
<img src="./images/preprocess.png" width="450">
#### Network Architecture
According to [1], I first preprocessed the 游戏 screens with following steps:
1. Convert image to grayscale
2. Resize image to 80x80
3. Stack last 4 frames to produce an 80x80x4 input array for 网络
The architecture of the 网络 is shown in the figure below. The first layer con the input image with an 8x8x4x32 kernel at a stride size of 4. The output is then put through a 2x2 max pooling layer. The second layer con with a 4x4x32x64 kernel at a stride of 2. We then max pool again. The third layer con with a 3x3x64x64 kernel at a stride of 1. We then max pool one more time. The last hidden layer consists of 256 fully connected ReLU nodes.
<img src="./images/网络.png">
The final output layer has the same dimensionality as the number of valid actions which can be performed in the 游戏, where the 0th index always corresponds to doing nothing. The at this output layer represent the Q function given the input state for each valid action. At each time step, the 网络 performs whiche corresponds to the highest Q value using a ϵ greedy policy.
#### Training
At first, I initialize all weight matrices randomly using a normal distribution with a standard de of 0.01, then set the replay memory with a max size of 500,00 experiences.
I start training by choosing actions uniformly at random for the first 10,000 time steps, without updating the 网络 weights. This allows the system to populate the replay memory before training begins.
Note that unlike [1], which initialize ϵ = 1, I linearly anneal ϵ from 0.1 to 0.0001 over the course of the next 3000,000 frames. The reason why I set it this way is that agent can choose an action every 0.03s (FPS=30) in our 游戏, high ϵ will make it flap too much and thus keeps itself at the top of the 游戏 screen and finally bump the pipe in a clumsy way. This condition will make Q function converge relatively slow since it only start to look other conditions when ϵ is low.
However, in other games, initialize ϵ to 1 is more reasonable.
During training time, at each time step, the 网络 samples minibatches of size 32 from the replay memory to train on, and performs a gradient step on the loss function described abo the Adam optimization algorithm with a learning rate of 0.000001. After annealing finishes, the 网络 continues to train indefinitely, with ϵ fixed at 0.001.
FAQ
#### Checkpoint not found
Change first line of sa/checkpoint to
model_checkpoint_path: "sa/bird-dqn-2920000"
#### How to reproduce?
1. Comment out these lines
2. Modify deep_q_network.py's parameter as follow:
References
[1] Mnih , Koray Ka, Da, Andrei A. Rusu, Joel , Marc G. Bellemare, Alex Graves, Martin Riedmiller, Andreas K. Fidjeland, Georg Ostrovski, Stig Petersen, Charles Beattie, Amir Sadik, Ioannis Antonoglou, Helen King, Dharshan Kumaran, Daan Wierstra, Shane Legg, and Demis Hassabis. Human-le through Deep Reinforcement Learning. Nature, 529-33, 2015.
[2] Mnih, Koray Ka, Da, Alex Graves, Ioannis Antonoglou, Daan Wierstra, and Martin Riedmiller. Playing Atari with Deep Reinforcement Learning. NIPS, Deep Learning workshop
[3] Kevin Chen. Deep Reinforcement Learning for Flappy Bird Report | Youtube result
Disclaimer
This work is highly based on the following repos:
1. [sourabh] ()
2. asrivat1/DeepLearning
项目信息
开发语言:Python
Star 数:6823
技术要点
该项目属于黑客技术方向的开源资源,代码结构清晰,适合安全研究人员学习参考。项目围绕Flappy Bird hack using Deep Reinforcement Learning (Deep Q-learning).展开,提供了可运行的实现,对理解相关安全机制、工具原理与攻防技术具有较高的研究价值。
从技术实现角度看,此类项目的核心在于对底层原理的深入理解与工程化落地。开发者在研究过程中可以结合官方文档与社区讨论,梳理项目的初始化流程、核心模块职责与数据流转,逐步掌握其中的技术细节与设计思路。
使用与学习建议
1. 下载源码压缩包,解压到本地环境。
2. 根据项目类型准备对应的运行环境与依赖。
3. 按照 README 中的步骤完成配置与部署。
4. 在隔离的测试环境中运行验证,避免影响生产系统。
免责声明
本资源来源于开源社区,仅供安全研究、技术学习与合法授权范围内的攻防演练使用,请勿用于任何非法或侵害他人权益的用途。使用本项目产生的一切后果由使用者自行承担。
| 资源标题 | DeepLearningFlappyBird - Flappy Bird hack using Deep Reinforcement Learning |
| 所属分类 | 黑客技术 |
| 发布作者 | admin |
| 发布时间 | 2026-10-05 22:29:54 |
| 下载权限 | 免费下载 |
| 附件数量 | 2 个下载链接 |
| 浏览次数 | 268 |
| 讨论数量 | 0 |
| 主题状态 | 正常讨论中 |