 安全软件
点击放大
crawlergo - A powerful browser crawler for web vulnerability s
项目说明
crawlergo
!chromedp ![BlackHat EU Arsenal]()
> A powerful browser crawler for web scanners
English Document | 中文文档
crawlergo is a browser crawler that uses chrome headless mode for URL collection. It hooks key positions of the whole web page with DOM rendering stage, automatically fills and submits forms, with intelligent JS event triggering, and collects as many entries exposed by the website as possible. The built-in URL de-duplication module filters out a large number of pseudo-static URLs, still maintains a fast parsing and crawling speed for large websites, and finally gets a high-quality collection of request results.
crawlergo currently supports the following features:
* chrome browser en rendering
* Intelligent form filling, automated submission
* Full DOM event collection with automated triggering
* Smart URL de-duplication to remove most duplicate requests
* Intelligent analysis of web pages and collection of URLs, including ja file content, page comments, robots.txt files and automatic Fuzz of common paths
* Support Host binding, automatically fix and add Referer
* Support browser request proxy
* Support pushing the results to passive web scanners
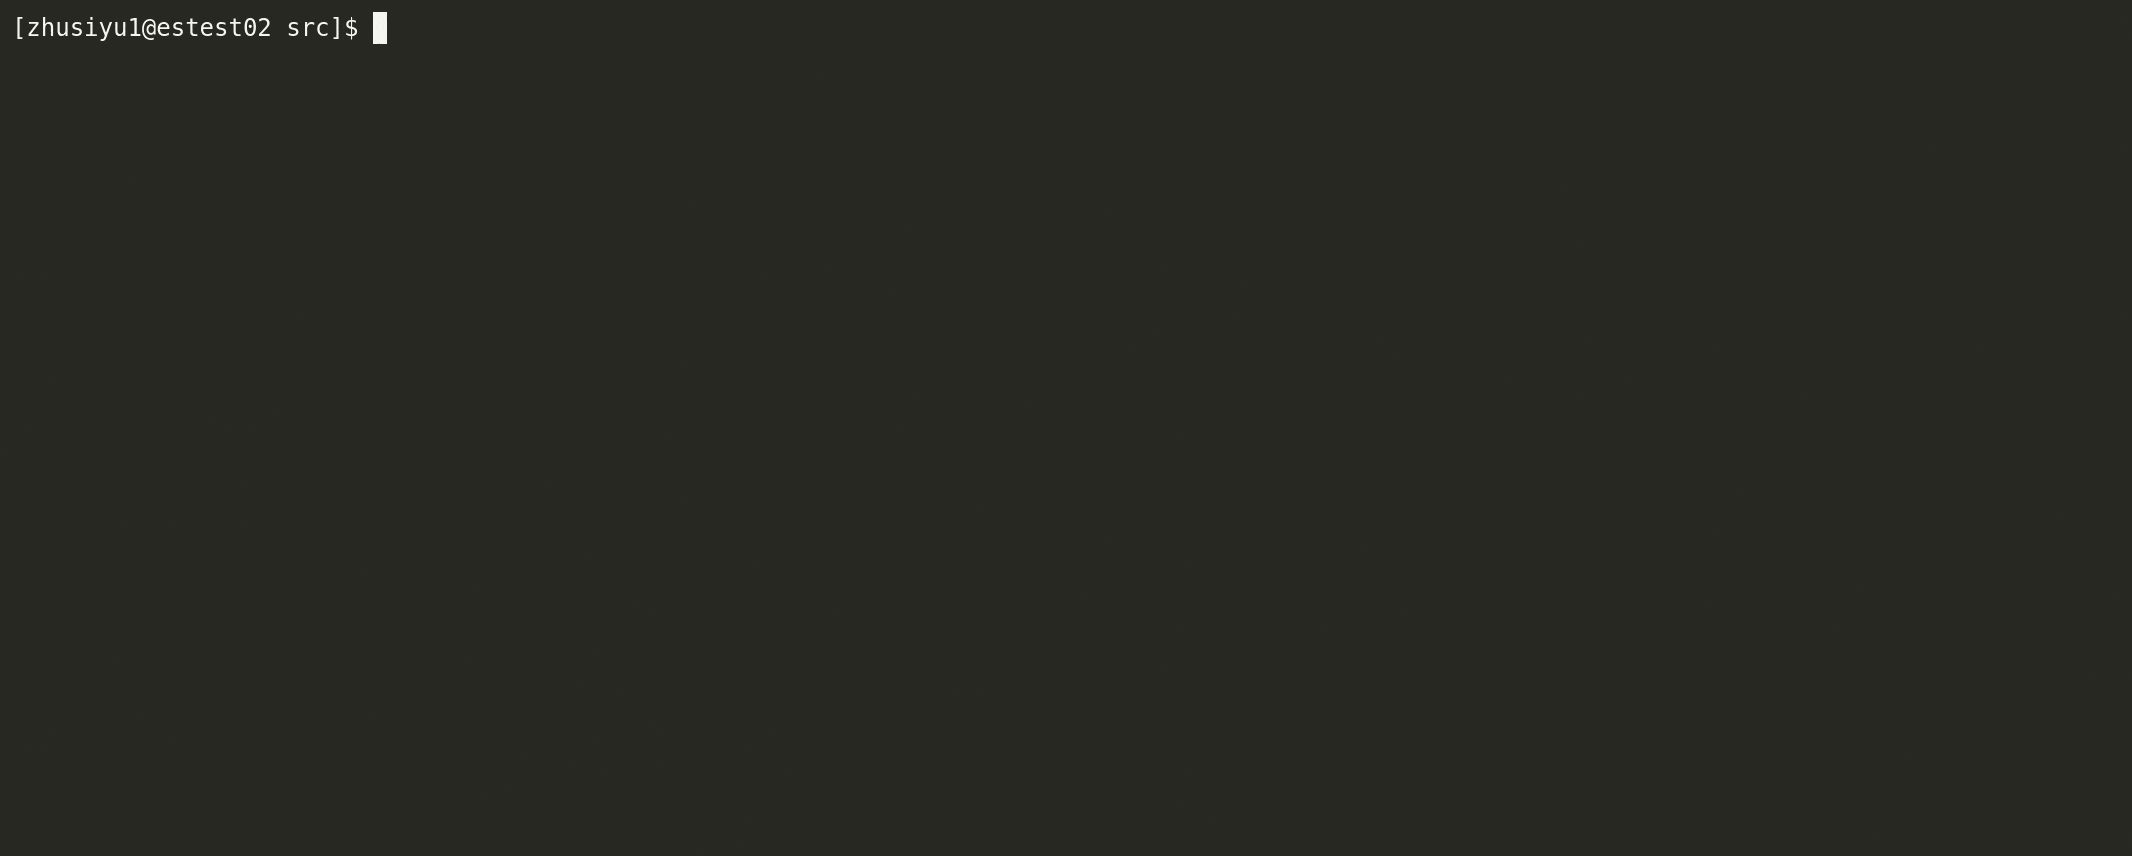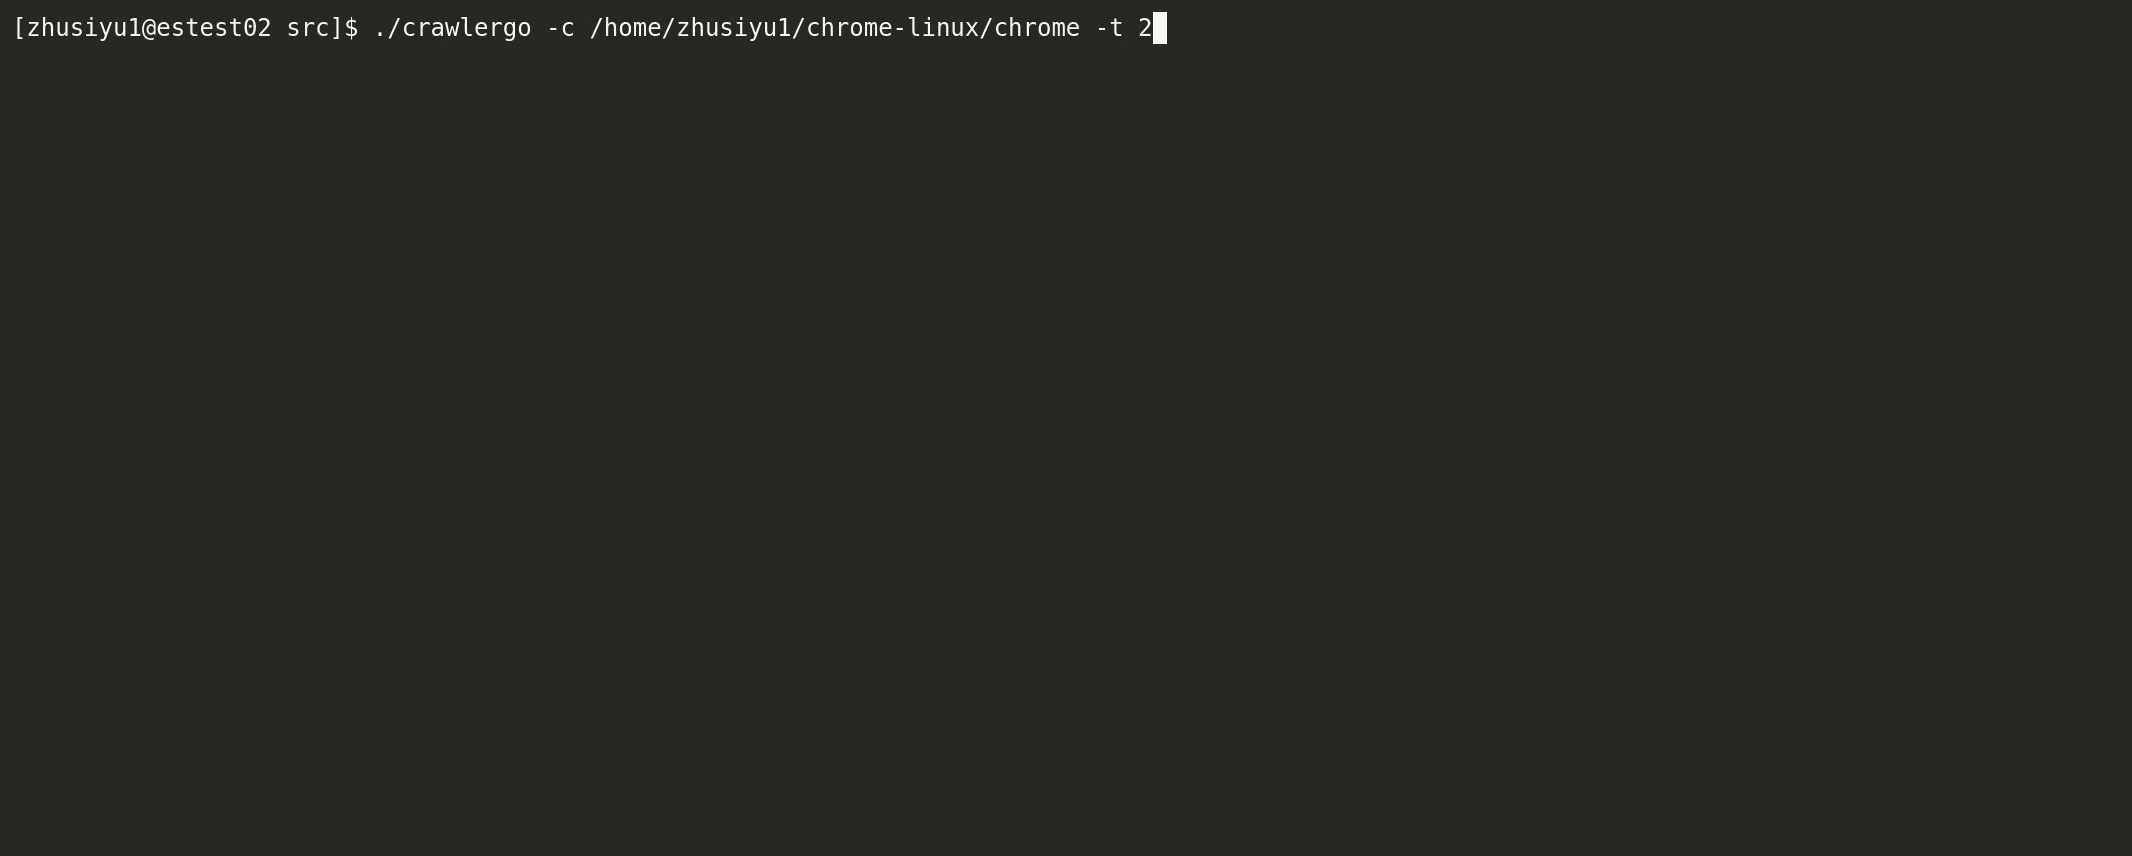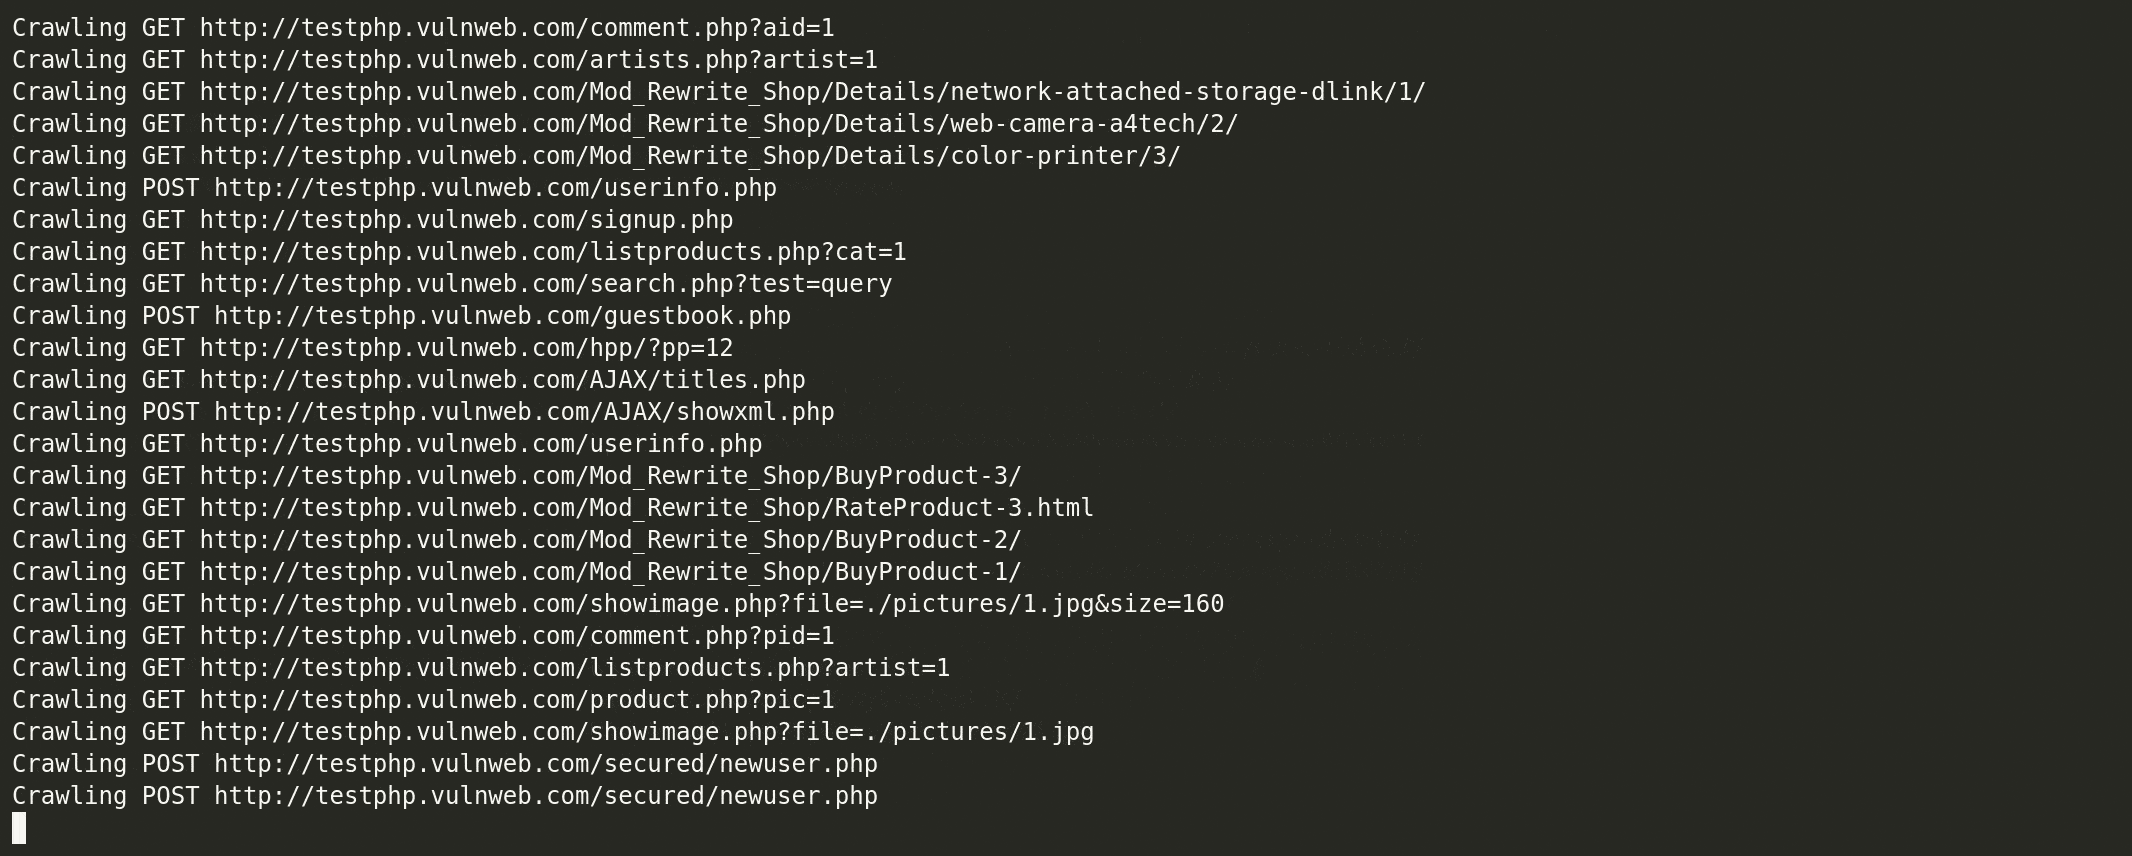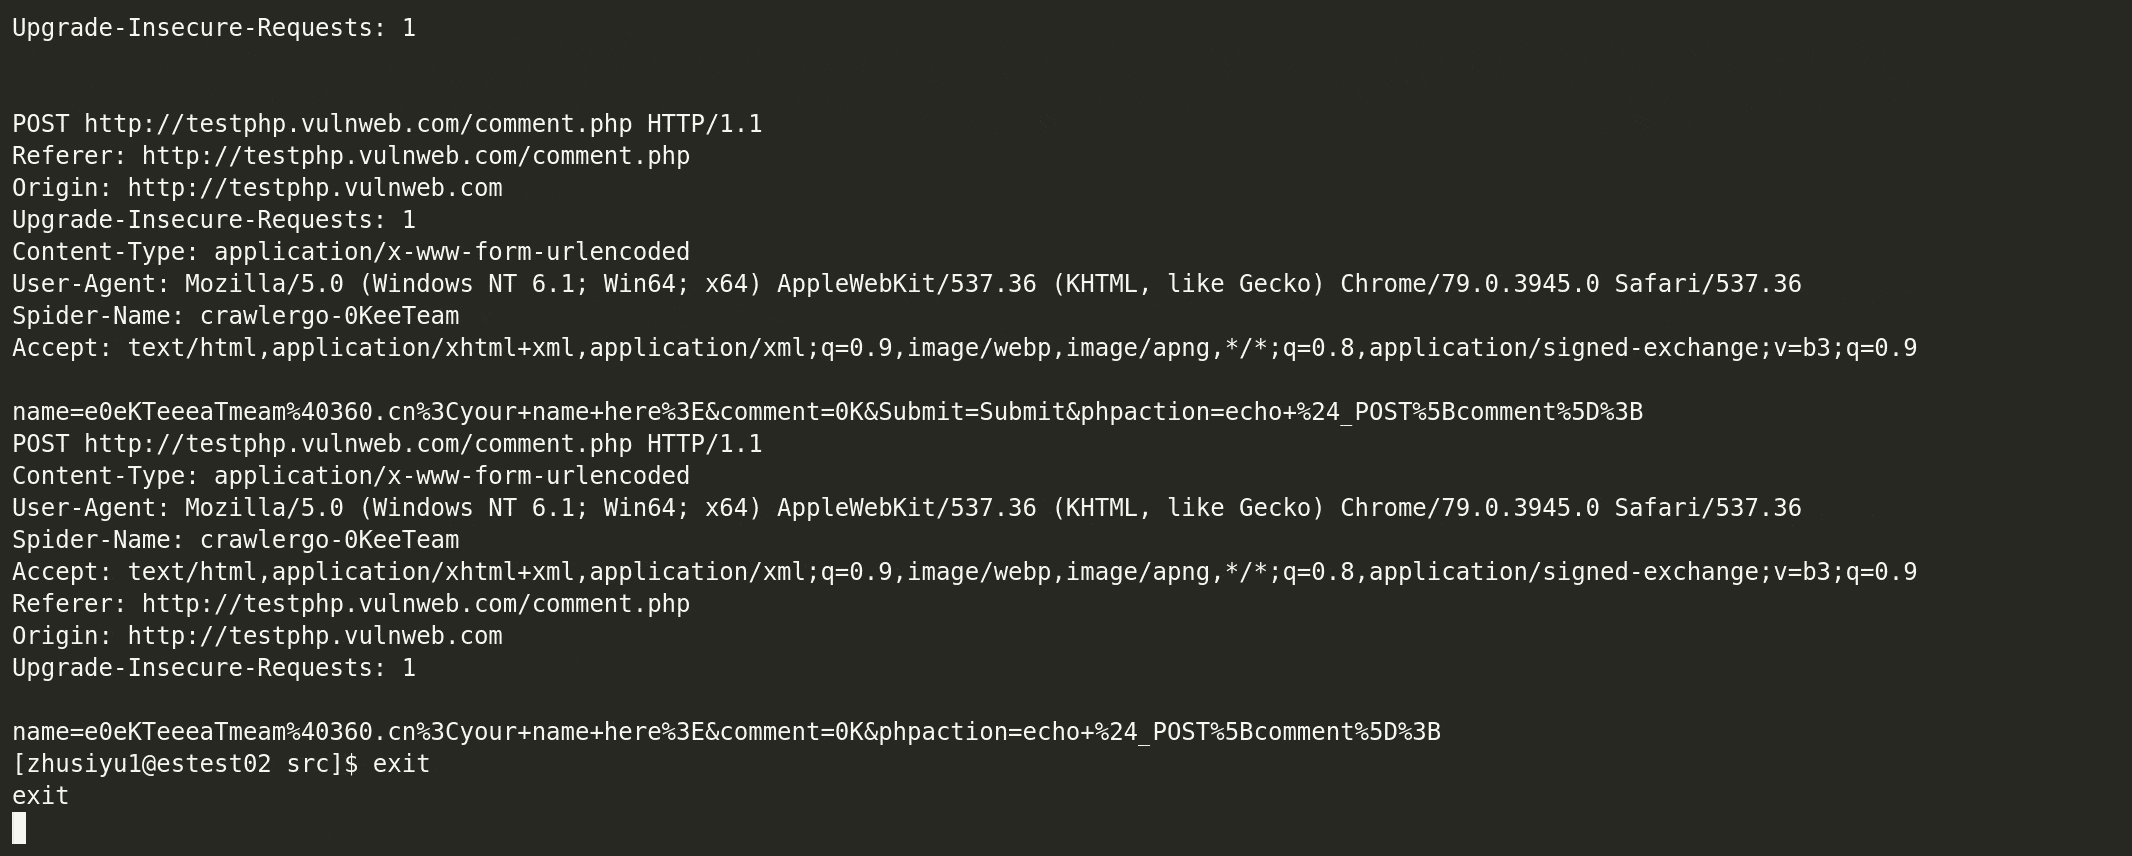
Screenshot

Installation
Please read and confirm disclaimer carefully before installing and using。
Build
1. crawlergo relies only on the chrome en to run, go to download for the new of chromium.
2. Go to download page for the latest of crawlergo and extract it to any directory. If you are on linux or macOS, please gi executable permissions (+x).
3. Or you can modify the code and build it yourself.
> If you are using a linux system and chrome prompts you with missing dependencies, please see TroubleShooting below
Quick Start
Go!
Assuming your chromium installation directory is /tmp/chromium/, set up 10 tabs open at the same time and crawl the testphp..com:
Docker usage
You can also use this with docker without headache:
Using Proxy
Calling crawlergo with python
By default, crawlergo prints the results directly on the screen. We next set the output mode to json, and the sample code for calling it using python is as follows:
Crawl Results
When the output mode is set to json, the returned result, after JSON deserialization, contains four parts:
* all_req_list: All requests found during this crawl task, containing any resource type from other domains.
* req_list:Returns the current domain results of this crawl task, pseudo-statically de-duplicated, without static resource links. It is a subset of all_req_list .
* all_domain_list:List of all domains found.
* sub_domain_list:List of subdomains found.
Examples
crawlergo returns the full request and URL, which can be used in a of ways:
* Used in conjunction with other passive web scanners
First, start a passi and set the listening address to:
Next, assuming crawlergo is on the same machine as the scanner, start crawlergo and set the parameters:
--push-to-proxy
* Host binding (not a for high chrome) (example)
* Custom Cookies (example)
* Regularly clean up zombie processes generated by crawlergo (example) , contributed by
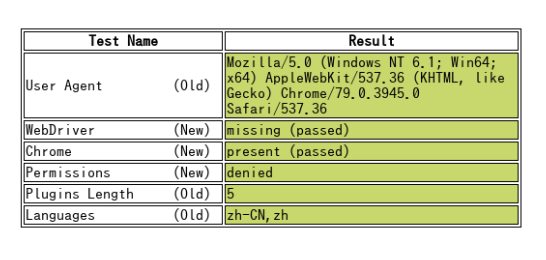
Bypass headless detect
crawlergo can bypass headless mode detection by default.

TroubleShooting
* 'Fetch.enable' wasn't found
Fetch is a feature supported by the new of chrome, if this error occurs, it means your is too low, please upgrade the chrome .
* chrome runs with missing dependencies such as xxx.so
* Run prompt Na timeout / browser not found / don't know correct browser executable path
Make sure the browser executable path is configured correctly, type: chrome:// in the address bar, and find the executable file path:

Parameters
Required parameters
*
--chromium-path Path, -c Path The path to the chrome executable. (Required)Basic parameters
*
--custom-headers Headers Customize the HTTP header. Please pass in the data after JSON serialization, this is globally defined and will be used for all requests. (Default: null)*
--post-data PostData, -d PostData POST data. (Default: null)*
--max-crawled-count Number, -m Number The maximum number of tasks for crawlers to avoid long crawling time due to pseudo-static. (Default: 200)*
--filter-mode Mode, -f Mode Filtering mode, simple: only static resources and duplicate requests are filtered. smart: with the ability to filter pseudo-static. strict: stricter pseudo-static filtering rules. (Default: smart)*
--output-mode value, -o value Result output mode, console: print the glorified results directly to the screen. json: print the json serialized string of all results. none: don't print the output. (Default: console)*
--output-json filepath Write the result to the specified file after JSON serializing it. (Default: null)*
--request-proxy proxyAddress socks5 proxy address, all network requests from crawlergo and chrome browser are sent through the proxy. (Default: null)Expand input URL
*
--fuzz-path Use the built-in dictionary for path fuzzing. (Default: false)*
--fuzz-path-dict Customize the Fuzz path by passing in a dictionary file path, e.g. /home/user/fuzz_dir.txt, each line of the file represents a path to be fuzzed. (Default: null)*
--robots-path Resolve the path from the /robots.txt file. (Default: false)Form auto-fill
*
--ignore-url-keywords, -iuk URL keyword that you don't want to visit, generally used to exclude logout links when customizing cookies. Usage: -iuk logout -iuk exit. (default: "logout", "quit", "exit")*
--form-, -fv Customize the value of the form fill, set by text type. Support definition types: default, mail, code, phone, username, password, qq, id_card, url, date and number. Text types are identified by the four attribute value keywords id, name, class, type of the input box label. For example, define the mailbox input box to be automatically filled with A and the password input box to be automatically filled with B, -fv mail=A -f=B.Where default represents the fill value when the text type is not recognized, as "Cralwergo". (Default: Cralwergo)*
--form-keyword-, -fkv Customize the value of the form fill, set by keyword fuzzy match. The keyword matches the four attribute of id, name, class, type of the input box label. For example, fuzzy match the pass keyword to fill 123456 and the user keyword to fill admin, -fkv user=admin -fkv pass=123456. (Default: Cralwergo)Ad settings for the crawling process
*
--max-tab-count Number, -t Number The maximum number of tabs the crawler can open at the same time. (Default: 8)*
--tab-run-timeout Timeout Maximum runtime for a single tab page. (Default: 20s)*
--wait-dom-content-loaded-timeout Timeout The maximum timeout to wait for the page to finish loading. (Default: 5s)*
--e Interval The interval when the event is triggered automatically, generally used in the case of slow target network and DOM update conflicts that lead to URL miss capture. (Default: 100ms)*
--e Value DOM event auto-triggered mode, with async and sync, for URL miss-catching caused by DOM update conflicts. (Default: async)*
--before-exit-delay Delay exit to close chrome at the end of a single tab task. Used to wait for partial DOM updates and XHR requests to be captured. (Default: 1s)Other
*
--push-to-proxy The listener address of the crawler result to be received, usually the listener address of the passi. (Default: null)*
--push-pool-max The maximum number of concurrency when sending crawler results to the listening address. (Default: 10)*
--log-level Logging levels, debug, info, warn, error and fatal. (Default: info)*
--no-headless Turn off chrome headless mode to the crawling process. (Default: false)Follow me
Weibo:@9ian1i
Twitter: @9ian1i
Related articles:A browser crawler practice for web scanning
项目信息
开发语言:Go
Star 数:3041
技术要点
该项目属于安全软件方向的开源资源,代码结构清晰,适合安全研究人员学习参考。项目围绕A powerful browser crawler for web vulnerability scanners展开,提供了可运行的实现,对理解相关安全机制、工具原理与攻防技术具有较高的研究价值。
从技术实现角度看,此类项目的核心在于对底层原理的深入理解与工程化落地。开发者在研究过程中可以结合官方文档与社区讨论,梳理项目的初始化流程、核心模块职责与数据流转,逐步掌握其中的技术细节与设计思路。
使用与学习建议
1. 下载源码压缩包,解压到本地环境。
2. 根据项目类型准备对应的运行环境与依赖。
3. 按照 README 中的步骤完成配置与部署。
4. 在隔离的测试环境中运行验证,避免影响生产系统。
免责声明
本资源来源于开源社区,仅供安全研究、技术学习与合法授权范围内的攻防演练使用,请勿用于任何非法或侵害他人权益的用途。使用本项目产生的一切后果由使用者自行承担。
| 资源标题 | crawlergo - A powerful browser crawler for web vulnerability s |
| 所属分类 | 安全软件 |
| 发布作者 | admin |
| 发布时间 | 2026-10-05 22:32:39 |
| 下载权限 | 免费下载 |
| 附件数量 | 2 个下载链接 |
| 浏览次数 | 162 |
| 讨论数量 | 0 |
| 主题状态 | 正常讨论中 |