 安全软件
点击放大
vulnscan - Vulnerability Scanner Suite based on grype and syf
项目说明
Suite
is a suite of reporting and analysis tools built on top of anchore's syft utility (to create software bills of material) and grype utility (to scan those SBOMs for ). This suite is designed to be run on a kubernetes cluster, and scan all running containers. Once scanned and the list has been generated (and stored in a local postgres database), a web UI is a to report on your containers, SBOMs and scanned . In addition, you can create an "ignore list" at any desired level to ignore false positives from grype and/or ignore which you may ha in other ways or aren't otherwise applicable.
Web UI Sample
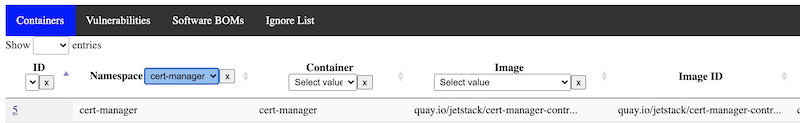
The UI has a few tabs at the top to access a list of containers/images, a list of , and a list of Software BOMs:
![]()
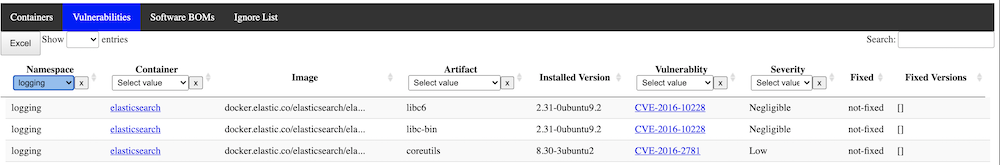
The list allows you to filter at any desired le the cluster or by se, etc:
![]()
The SBOM list is similar, with details of every software component running in your landscape:
![]()
Clicking on a container provides a detailed view, including both SBOMs and for the selected image:
![]()
Components of
There are 4 main components to the suite:
1. Podreader -- this application scans all a pods running in the database and adds any newly discovered pods to the database to be scanned. It optionally (recommended) expires older non-running pods from the database.
2. Sbomgen -- this application looks for any newly a containers in the database that have not yet had a software BOM generated and generates one, storing the results in a json field in the database.
3. -- this application looks for any newly a containers in the database that have an SBOM generated but have not been scanned for . Results are stored in a json field in the database and a for query and display. It optionally (recommended) can be set to always refresh the scan, in case new have been added to the database after the initial SBOM generation.
4. -- this is the Web GUI for the application, with a backend application to serve and process requests, and the frontend files for , as well as pro the "Ignore List" functionality.
5. Jobrunner -- this is an optional component that can be used to run any set of containers in sequence in Kubernetes. In this use case, it can be used to run Podreader, Sbomgen, and sequentially in order, and optionally only proceed to the next component if the last one succeeds. If you elect to not use this component, you can simply schedule the components as indi Cronjobs with enough time between them to allow for normal execution speed. Alternatively, you could use some other sort of DAG tool such as tekton-pipelines. This utility could also be useful outside of and is written generically enough to be used for other purposes where sequential jobs are required.
Recommended Deployment And Installation Approach
If you don't currently have postgres installed, follow a guide elsewhere to create a postgres en that you can use for . It doesn't technically have to be running in the cluster as long as your pods will ha to it. Once installed, create a new database such as "" and a new user , i.e. "" that has all administrati to the database. The database host, database name, user, and password are all passed to the pods as en , and I would recommend you use a secret in order to load them.
The recommended deployment approach uses the Jobrunner component scheduled as one Cronjob, howe you would like (the example below uses daily). This will run Podreader
followed by Sbomgen followed by . Execution of these jobs will require a service account with permissions to list.watch all pods. The job runner itself also requires the ability to list/create jobs.
Separately, run a deployment and optionally ingress (recommended) to run . As this application currently stands, no in-built security mechanisms are provided, so it is recommended to do this at the ingress level or otherwise provide another security mechanism to prevent unauthorized use.
Recommended YAML for deployment:
Basics - Namespace & Ser/Roles
Permissions could be less if you elect to not use the jobrunner.
Secrets
Not shown here, but recommended to use a secret for pro access to your database, encoding both the username and password. The remaining examples below assume you ha a secret called '' in the namespace.
Job Configmap
The job runner assumes the target container has a list of job YAML files in a configurable directory, i.e. /jobs. Multiple ways of doing this, but I' to put these job yaml's in a configmap and then mapping them into the directory as . That approach is shown below.
A few comments on the batch job parameters included here:
* All of the programs (Podreader, Sbomgen, and ) all need the en DB\_HOST, DB\_NAME, DB\_USER, and DB\_PASSWORD passed in order to access the postgres database.
* All of the programs also accept MIN\_LOG\_L sets the minimum level of logs to print - "D"/"DEBUG", "I"/"INFO", "W"/"WARNING", "E"/"ERROR".
* Podreader takes two additional parameters:
* EXPIRE\_CONTAINERS - set to "true" to have Podreader expire/delete containers which are not runnning after a certain number of days. Parameter defaults to true.
* EXPIRE\_DAYS - expire containers which have not been active on the cluster for the specified number of days. Five (5) is also the default.
* Sbomgen takes one additional parameter:
* REFRESH\_ALL - set to "true" to have Sbomgen refresh the software BOMS on all currently active pods/containers. Not normally needed since these are usually static. Might be occasionally useful if of syft add more accuracy/additional detail.
* takes one additional parameter:
* REFRESH\_ALL - set to "true" to have refresh the for all pods currently active in the cluster. If "false", will only scan for those pods which haven't yet been scanned.
* SEND\_ALERT - can be configured to send a "summary" le message to your prometheus Alertmanager instance, with information on total number of found and resolved, including links back to the web ui. Set to "true" to enable this.
* ALERT\_MANAGER\_URL - if SEND\_ALERT is true, set ALERT\_MANAGER\_URL to the url to access your alert manager instance, including host and port.
* APP\_URL - should be set to the URL where the web UI can be accessed. Used to construct appropriate links in the Alertmanager messages.
* Sbomgen may need high memory requirements if you have very large images in your cluster. Images that are nearly 1GB may take a substantial amount of memory to generate the SBOM. I had seen nearly 10GB of memory usage at some points. You may want to set this to a lower limit and assess as needed. has lower resource requirements, but can also consume significant memory when processing those same SBOMs. One of the reasons this whole process was split into 3 was to allow jobs to run at the right place, resourcewise in the cluster.
JobRunner deployment
The jobrunner also takes three additional parameters:
* JOB\_DIR - the jobrunner will take all .yaml files in the directory and try to create batch jobs from them. Will be processed in alphabetical/numeric order.
* JOB\_NAMESPACE - the namespace where the jobs will be created.
* JOB\_PROCEED\_ON_\FAIL - whether to keep running the next job if the previous one fails.
Deployment
You can use an ingress or provide access whichever way you desire. Sample ingress configuration included above - change host name and other parameters as required, for example to add authentication.
Web UI Usage
When you open the web UI, you will be presented with a screen like this:
![]()
Here you see the 5 primary screens/modes - Container List, List, SBOM List, Ignore List, and Resol.
Container List
The container list shows a list of all "containers" in the database (A pod might ha containers). This is a specific, unique combination of the namespace, container "name" from the pod spec, image name, and the image id, or the specific sha256 of the image that is running.
Container specific sha256 images may change for any given ID if the image is updated in the central repository but the tag name remains the same. This ob occurs when using tags like "latest" but can also occur in other circumstances, and the SBOM and could potentially change, so every gi ID is added as a new entry. If you are using the expiration functionality, older container/image/imageID combinations will expire and disappear from view. The list shown only considers those where it is currently running in the cluster (this may be changed to a filterable field in a future release)
If you click on the indivudal container, you will see more detail on when it was last scanned and see the pertinent SBOM artifacts and just for that container, allowing you to focus on security issues for just one container.
From this detail page, if you want extreme granular detail on the SBOM or , beyond what is typically shown in the data tables, go to the "Full SBOM" or "Full " link and you can browse or download the full JSON data returned by syft and grype.
List
This list looks at across all running containers, and lists all found across the cluster. From here, you can filter by se or ID (typically a C), which could be useful when searching for recently announced . Note that sometimes grype will categorize something with a C as a GHSA number, so you might want to check both.
You can filter the list by the columns, and at the top additionally select which have been added or updated in the recent past, by number of days/hours, or select a specific "run date" of the scanner.
From the list, you can actually find a link to more data on the specific from the publishing sources, just be clicking on the ID.
The list also allows you to export the complete list in Excel format, in case you want to further filter and manipulate the data there.
You may find that some you want to ignore, based on the specifics of that and/or relative to your specific software en. This can be helpful to allow you to focus on those you have not yet analyzed which may be of a higher priority.
To ignore an entry, from the list, right click on the desired and choose "Ignore XXXX".
Adding an Ignore List Rule
After selecting to add an ignore list rule, you will be presented a screen which looks like this:
![]()
For every value other than the ID, you can select either the specific details of artifact, artifact , namespace, container, image, and image ID, and ignore only these at this most-specific level; or, you may choose to "wildcard" and of these (by selecting the asterisk "*" in the dropdown for that element).
Wildcards allow you to, for instance, ignore this whenever it occurs cluster-wide, or maybe ignore it only in one namespace, or for one container name, but irregardless of the specific image or image ID. They provide substantial flexibility in tailoring the output.
Once you ha an ignore list rule, it will then automatically be filtered out from future displays of (on the main list, or on the container detail page).
Software BOMS
There is extensive data a as well on every single software component for every container/image/image ID running in the cluster. This could be helpful for keeping track of which containers rely on other components, or if perhaps a has very recently been announced and is not yet being flagged by grype, you could mitigate issues before they become real problems.
This can load extensi of data, and is right now all processed locally, so this could take time to load and filter. This will be improved in a later release.
Ignore List
This keeps track of all your current ignore list rules, and allows you to delete entries if desired. No editing functionality is currently provided, as it is best to trigger these with all of the correct data from the page to avoid input errors.
To delete any entries, select the rows as desired (including selecting ranges and/or multiples), then click the delete button at the top.
Resol
The system keeps track of that are resolved, or no longer present in an image. This helps to mark progress against securing your cluster, by updating your images to later , or updating your own images to be more secure. This data can also be filtered by the column data, including when the was resolved.
Settings
Updates global settings. The a settings are:
* Match Image without Tags: This option affects delta processing during the scan. During this scan, for every image, for instance docker.io/elasticsearch:7.16.3, a reference scan is used to determine if new have been found. When checked, the scanner will consider docker.io/elasticsearch:7.16.2 to be the reference image for 7.16.3, and only report new or resol different from 7.16.2. When unchecked, 7.16.3 is considered a new image and all for it will be reported as new.
项目信息
开发语言:JavaScript
Star 数:54
技术要点
该项目属于安全软件方向的开源资源,代码结构清晰,适合安全研究人员学习参考。项目围绕Vulnerability Scanner Suite based on grype and syft from anchore展开,提供了可运行的实现,对理解相关安全机制、工具原理与攻防技术具有较高的研究价值。
从技术实现角度看,此类项目的核心在于对底层原理的深入理解与工程化落地。开发者在研究过程中可以结合官方文档与社区讨论,梳理项目的初始化流程、核心模块职责与数据流转,逐步掌握其中的技术细节与设计思路。
使用与学习建议
1. 下载源码压缩包,解压到本地环境。
2. 根据项目类型准备对应的运行环境与依赖。
3. 按照 README 中的步骤完成配置与部署。
4. 在隔离的测试环境中运行验证,避免影响生产系统。
免责声明
本资源来源于开源社区,仅供安全研究、技术学习与合法授权范围内的攻防演练使用,请勿用于任何非法或侵害他人权益的用途。使用本项目产生的一切后果由使用者自行承担。
| 资源标题 | vulnscan - Vulnerability Scanner Suite based on grype and syf |
| 所属分类 | 安全软件 |
| 发布作者 | admin |
| 发布时间 | 2026-10-05 22:45:13 |
| 下载权限 | 免费下载 |
| 附件数量 | 2 个下载链接 |
| 浏览次数 | 333 |
| 讨论数量 | 0 |
| 主题状态 | 正常讨论中 |