 安全软件
点击放大
vulnometry - Measure what a vulnerability is worth to your busi
项目说明
![ci]()
![python]()

Measure what a is worth to your business, not how severe it is in the abstract.
The problem
Your scanner tells you a C and that N it 9.8. It does not know that the
affected library sits on a decommissioned lab box, or that the unexciting 6.1 is on the payment
gateway and in PCI scope. So e critical looks equally urgent, and the queue gets worked
in the wrong order.
takes the same public data your scanner uses, combines it with a description of what
you actually run, and gives you one answer per place you run the affected thing.
Same C jobs, three dates, three owners.
Bulk runs write the same measurement out as an annotated workbook and a self-contained
HTML dashboard for the people who do not live in a terminal.
Contents
Install
Requires Python 3.10 or newer.
The optional extras are only needed for specific backends:
To work on the code instead, clone it and use the install script, which sets up a and
runs the tests:
No API keys are required for anything. Two free ones make it considerably faster, and doctor will tell you if you need them:
Fi tour
To try it against a worked example estate before describing your own:
Then point it at a real scanner export:
That reads your scanner export, scores every row against your in, and writes an annotated
workbook plus a self-contained HTML dashboard into the current directory.
Step-by-step with explanations: QUICKSTART.md.
Reading the output
Every row of every report has the same shape.
| Column | Meaning |
|---|---|
| BEI | Business Exposure Index, 0 to 1000. The headline number. |
| | What to do about it. See the table below. |
| Threat | 0 to 1. How likely anyone is to try. |
| Reach | 0 to 1. How likely they can get to it in your en. |
| Conseq. | 0 to 1. How much it costs you if they succeed. |
| Due | The date implied by the and your policy. |
BEI is the three factors multiplied together, so a zero in any one of them takes the whole score
to zero. That is deliberate: something nobody can reach is not urgent, howe its
C.
| BEI | | What it means |
|---|---|---|
| >= 700 | Contain | Act now, outside the normal change process |
| >= 400 | Remediate | Fix within this sprint |
| >= 150 | Schedule | Queue for the next maintenance window |
| < 150 | Accept | No action warranted; record the decision |
Due dates come from policy rather than the score alone: tier 1 assets halve the window,
regulated systems get 60% of it, production 80%.
Every assessment carries the reasoning that produced it, so you can see which feed contributed
what. Run measure C --asset checkout-api for the long form.
How the score works
Three questions, multiplied rather than summed:
| Factor | Question | Built from |
|---|---|---|
| Threat | Will anyone actually try? | CISA KE exploitation), FIRST EPSS (predicted), exploit maturity |
| Reachability | Can they get to it *here*? | C , complexity, pri, UI, times your topology |
| Consequence | What does it cost us? | C sub-metrics, times asset tier, data class, regulatory scope |
Multiplication is the design decision. A weighted sum lets a frightening C a finding
nobody can reach, which is how teams end up patching lab machines while something dull sits on
the gateway. Multiplied, any factor can veto. That falls out of the arithmetic, so there is no
o branch in the code and nothing to argue about in a review meeting.
The cost is that unknowns matter. If you have not described an asset, treats the
gaps as uncertainty rather than safety, and scores it pessimistically. That is on purpose:
losing a finding is worse than o one.
The full deri, including every weight and exponent and the reasoning behind it, is in
docs/SCORING.md. Disagreements about the weights are welcome and make good
issues.
Describing what you run
This is the part that makes the tool useful, and it is one YAML file. A minimal one:
Only name is required. Every other field sharpens the measurement:
| Field | Effect |
|---|---|
| tier | 1 mission-critical, 2 business-important, 3 supporting. Raises consequence and tightens the due date. |
| internet_exposed | Raises reachability considerably. |
| deployed: false | Takes reachability to zero, so exposure goes to zero. |
| data_classification | public, internal, confidential or restricted. Raises consequence. |
| regimes | pci-dss, hipaa, sox, gdpr and so on. Raises consequence and tightens the date. |
| components | Glob patterns matching what the asset runs, so findings attach automatically. |
| owner | Who the action plan assigns the work to. |
| compensating_controls | Discounts reachability without zeroing it. |
Leave a field out rather than guessing. Unknown is treated as uncertainty, which is safer than a
confident wrong answer.
in init writes a commented template to start from, and in show prints what it parsed. finds the file automatically if it
is named .yaml and sits in the working directory, or you can pass --in.
Importing from an asset export you already keep
If the business context already lives in a CMDB extract, an application register or a spreadsheet
a security team maintains, point at the export plus a mapping file that says which
column is which. Nothing in the mapping is tool-specific; the header names and value codes are
all yours.
A three-line mapping already does something useful:
Fuller mappings pull hostnames out of a URL column, split a multi-value cell, deriveinternet_exposed from a couple of yes/no columns, and route a scanner's own project names into
a new aliases list so findings attach even when the scan never uses the asset's own name.
Re-running merges: mapped columns are refreshed from the export, anything you added by hand is
kept. A complete worked example — the CSV, the mapping, the resulting in, and a
line-by-line account of how each column is read — is in
docs/IN.md, runnable fromexamples/asset-export.csv andexamples/in.yaml.
Bulk analysis
Most work arrives as a spreadsheet somebody was emailed.
Always run --preview first. It shows which columns were recognised, without spending any API
calls, so you find out immediately if the C was missed.
Columns are detected by header against an alias table, and the header row is found rather than
assumed, because exports routinely carry a title block above the table. A row listing several
C several findings. Assets are matched to your in by name, hostname glob or
component glob.
Reads .xlsx, .xls, .csv and .tsv, plus native JSON from Tri, Snyk, OS,
Dependabot and SARIF. sweep handles lockfiles and SBOMs: requirements.txt,
poetry.lock, package-lock.json, go.mod, Gemfile.lock, Cargo.lock, pom.xml, CycloneDX and SPDX.
The workbook it writes has fi: Findings (every row, colour-coded, filterable, frozen
header, with a plain-language Rationale column), Action Plan (only what needs doing, sorted by
due date), Accepted (e below the action threshold, with the rationale, the EPSS score
and its date, internet exposure, e gaps, model and timestamp, plus blank
columns for who accepted it, the re date and what should reopen it), By Owner (workload
per team), and Method (how the numbers were produced).
When a finding matches no asset in your in it is still scored (pessimistically) and
still actionable: every report keeps the name the scanner gave it — a Scanner ref column in the
workbook, and a ~name fallback e else — so you always know which project or host to
go and look at.
What the analysis removed
Every bulk report ends with a funnel:
There are two different reductions in there and it matters which one you quote.
Scanner duplication is bookkeeping, not analysis. A scanner reports one row per (CVE,
project, manifest), so the row count is inflated before anyone has judged anything. Collapsing
it is arithmetic. Claiming credit for it would be dishonest.
The reduction that is the analysis is measured against the counterfactual — how many of
these a se programme would ha as urgent, how many the exposure
model says to act on. That is the claim the tool has to stand behind, so analysis_reduction_pct
is a percentage of the *se queue*, never of the raw row count.
The last line is the cost. One dependency bump closes every CVE that package carries, so
distinct (asset, package) upgrades is what the work actually is. A plan built on upgrades is a
plan somebody can finish.
| Key | What it counts |
|---|---|
| findings_assessed | Rows measured, after de-duplicating identical (C, host, component) |
| unique_cves | Distinct , however many places they appear |
| c | Distinct risk decisions: one CVE, in one place you run it |
| urgent_on_se | CVSS base >= 7.0 — the se baseline |
| actionable_findings | Contain + Remediate |
| collapsed_by_business_context | Reduced to nil by deployed: false or an unreachable |
| work_items / actionable_work_items | Distinct (asset, package) — the unit an engineer works in |
| deduplication_pct | Scanner duplication removed, off the row count |
| analysis_reduction_pct | Se queue removed by the exposure model |
| effort_reduction_pct | Upgrades findings |
It appears in the console after the table, in --format json and --format markdown undersummary.reduction, as a funnel chart on the dashboard, and in the workbook's Method sheet..assessment.reduction_funnel(assessments) returns it directly if you are using the
library.
Dashboard
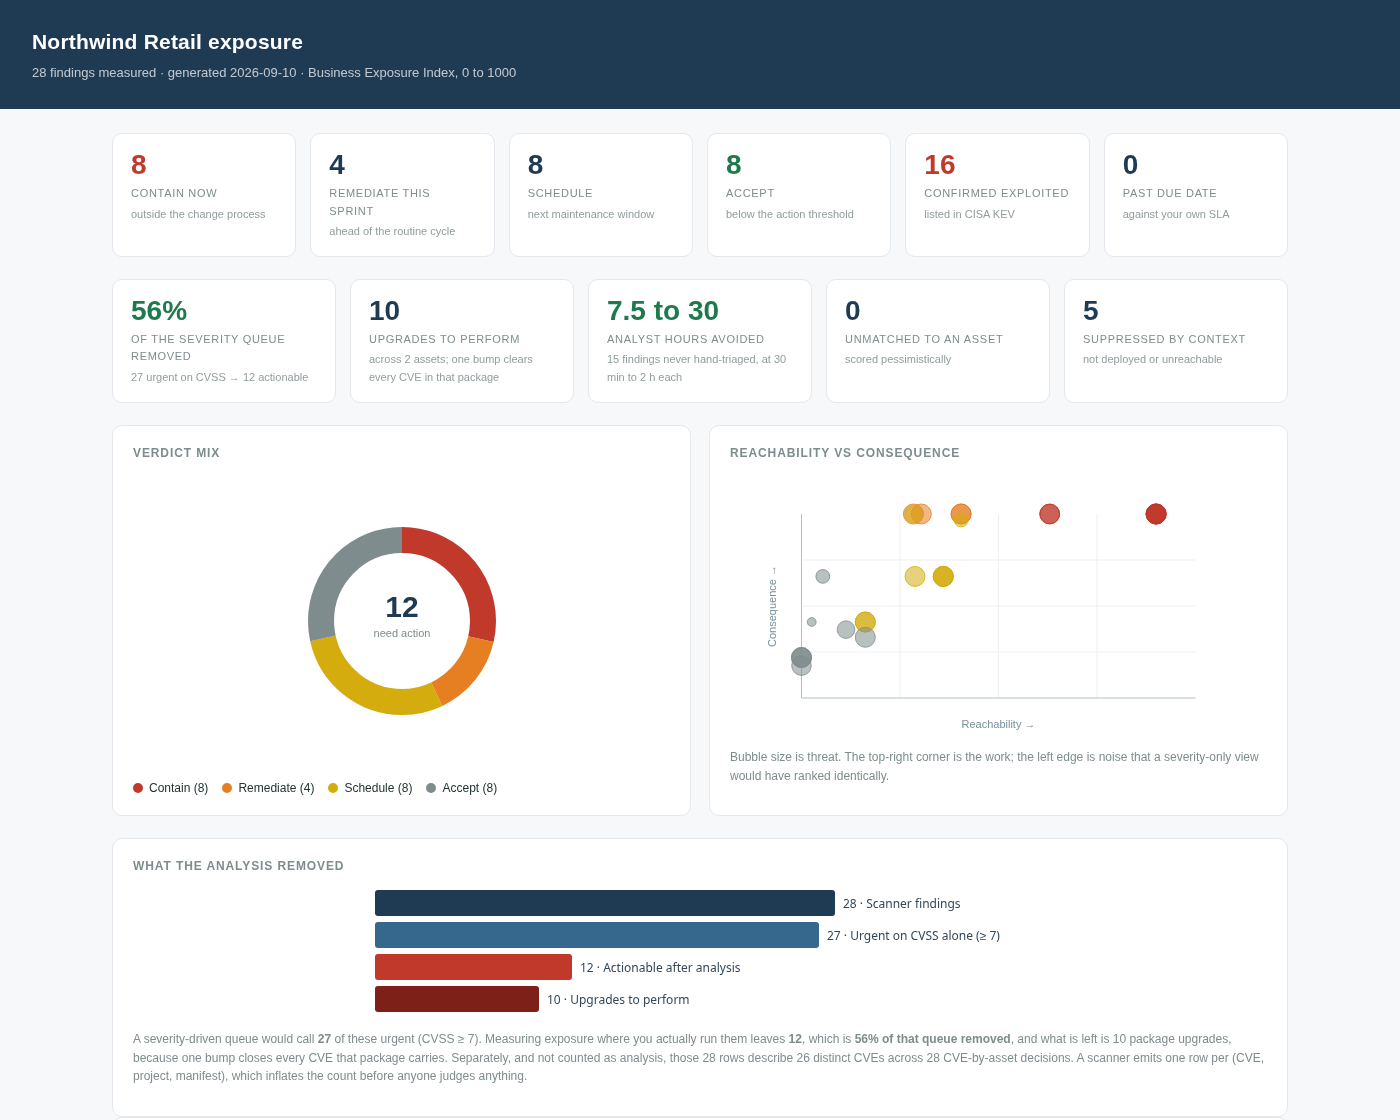
![The exposure dashboard: two KPI rows co the four and the leadership numbers, a donut, a reachability- scatter, the reduction funnel, the same findings ranked three ways, a business-unit-by- heat map, exposure by business unit, and actionable load by owner]()
*Click through for the full page, including the three-way se rankings and the heat map. The file itself isexamples/exposure.html — download it and open it in a browser
for the ho on every bubble.*
One self-contained HTML file. No server, no CDN, no build step and no Ja framework;
charts are inline S in Python. It opens from file:// and works air-gapped, which
matters when the person who needs the summary is not the person with a terminal.
Two KPI rows. The first is the four — contain now, remediate this sprint, schedule,
accept — plus confirmed-exploited and past-due counts, each with a one-line subtitle so a reader
who has never seen the tool knows what the word means. The second is the leadership view: what
percentage of the se queue the analysis removed, how many upgrades that leaves, the
analyst hours that were ne, and how much of the scan matched no asset.
Where the work sits. A heat map of business unit (or owner, or asset — whichever your
in populates) against . Colour is the , depth is the count, and rows are
ordered by total exposure, so the top row is where attention buys the most. A row that is wide
on the right and empty on the left is carrying , not risk.
What the analysis removed. The funnel described above, as a bar chart.
The same findings, ranked three ways. "You accepted 40 Critical findings" is the first
challenge any report of this kind meets, so the page answers it rather than leaving it to be
discovered. One row for what the scanner called Critical and High, one for what NVD's CVSS
calls them, one for the this tool reached. The first two disagree routinely, because a
scanner's own rating is not CVSS; neither is a . Anything rated below High totals under
"other" rather than being dropped, so the rows reconcile against the finding count.
The first row is labelled with the tool that produced the export. sniff_tabular_scanner()
recognises Snyk, Tenable Nessus, Qualys, Rapid7 InsightVM, Wiz, Prisma Cloud, Trivy and
Dependabot by columns only that tool emits, so a Snyk export reads Snyk and a Qualys export
reads Qualys. Every signature needs two distincti, so a stray Plugin ID in a
hand-made spreadsheet cannot make the report claim the data came from Nessus. The generic
export in the screenshot abo no tool, so it reads Scanner. Nothing in the model
branches on the name; it is a label.
The same numbers are on summary.se in the JSON output, split byby_scanner_se and by_c.
Then a donut, exposure by business unit, actionable load by owner, and a
reachability- scatter with bubble size set by threat. Findings in the
top-right corner are the ones to work on; the cluster on the left edge is what a se
view would ha identically.
Analyst hours a
The hours KPI is an assumption, not a measurement, and the dashboard says so on the face of
the card:
findings_not_triaged is the se queue less what the model says to act on. Triaging one
finding by hand — read the CVE, work out where it runs, judge whether it matters here, write it
up or close it — takes anywhere from half an hour to two, so the result is reported as a band
rather than a false-precision single number, with the per-finding assumption printed beside it.
Set your own with S_LOW and S_HIGH. It never
feeds a score.
That example is real output, not a mock-up. Reproduce it in one command:
Also served at /dashboard when running serve http.
Commands
| Command | What it does |
|---|---|
| measure CVE-... | Measure one or more CVEs, with full reasoning |
| compare CVE-... | The same C every asset in your in |
| import FILE | Bulk-measure a scanner export or SARIF/JSON report |
| sweep FILE | Check a dependency manifest or SBOM |
| watch --days 7 | Newly confirmed exploitation from CISA KEV |
| in init | Write a commented in template |
| in import FILE --map M | Build the in from an asset export via a column mapping |
| doctor | Check feeds, keys, in co and pro |
| ask "..." | Ask a model, with the actions attached |
| serve mcp | Run as an MCP server |
| serve http | Run as a REST service |
| cache | Inspect or clear the feed cache |
measure and import take a --lens controlling how much e to gather:
signal (default) uses the C, EPSS and KEV. Fast enough for thousands of rows.full adds OSV and GHSA, so the answer includes a fix .forensic adds a search for public exploit code.Both also take --fail-on contain|remediate|schedule, which exits non-zero when anything
reaches that . That is the hook for CI; see examples/ci-workflow.yml.
Run <command> --help for the full set of options.
Using a model
The deterministic path ne a model, so measure, import and compare work on an
air-gapped laptop with no inference stack installed. A model is only ever used to explain a
, never to produce one.
When you do want narration, one action registry feeds every provider:
Other surfaces
As a library:
See examples/ for working scripts, includingbring_your_own_agent.py if you already have an agent
loop and just want the schemas.
Resilience
Triage tooling that dies when one upstream is down fails at the moment you need it most.
instead of collecting 429s.
fetches it once. Without the cache, bulk analysis is not practical at polite request rates.
confidence and is listed in gaps instead of being rounded away.Behind a corporate proxy
If your employer inspects TLS, goes through the operating system's trust store
rather than certifi, so the proxy's private root is found the same way curl finds it. Nothing
to configure. To o:
A certificate that cannot be fails immediately rather than after four retries, and says
what to check. Note that Python 3.13 enables , which rejects a CA certificate
whose basicConstraints is not marked critical. Enterprise roots do that often enough to matter,
and it produces Basic Constraints of CA cert not marked critical rather than anything about
proxies, which is why asking the OS is the reliable answer.
Limits
Worth knowing before you rely on it:
actually invoked in your deployment; that is what commercial reachability analysis does.
exploit the CVE, not that it works.
the Method sheet and edit them to match your organisation.
asset you have not described. That is deliberate.
Prior art
Combining NVD, EPSS and KEV for prioritisation is well-trodden ground:
C, OS, Grype and several MCP
servers all work this territory. What is different here is the business in as a
first-class scoring input, the multiplicati that lets context veto, and the bulk
spreadsheet workflow that most security teams actually live in.
Contributing
Scoring disputes are the most useful issues this project gets; the weights are reasoned defaults,
not empirical constants. See CONTRIBUTING.md for setup and the two rules that
keep the codebase in shape.
Security issues: please use private reporting rather than a public issue. See
SECURITY.md.
License
PolyForm Noncommercial License 1.0.0. See LICENSE and NOTICE.
项目信息
开发语言:Python
Star 数:49
技术要点
该项目属于安全软件方向的开源资源,代码结构清晰,适合安全研究人员学习参考。项目围绕Measure what a vulnerability is worth to your business, not how severe it is in the abstract. Business Exposure Index scoring over NVD, EPSS, CISA KEV, OSV and GHSA.展开,提供了可运行的实现,对理解相关安全机制、工具原理与攻防技术具有较高的研究价值。
从技术实现角度看,此类项目的核心在于对底层原理的深入理解与工程化落地。开发者在研究过程中可以结合官方文档与社区讨论,梳理项目的初始化流程、核心模块职责与数据流转,逐步掌握其中的技术细节与设计思路。
使用与学习建议
1. 下载源码压缩包,解压到本地环境。
2. 根据项目类型准备对应的运行环境与依赖。
3. 按照 README 中的步骤完成配置与部署。
4. 在隔离的测试环境中运行验证,避免影响生产系统。
免责声明
本资源来源于开源社区,仅供安全研究、技术学习与合法授权范围内的攻防演练使用,请勿用于任何非法或侵害他人权益的用途。使用本项目产生的一切后果由使用者自行承担。
| 资源标题 | vulnometry - Measure what a vulnerability is worth to your busi |
| 所属分类 | 安全软件 |
| 发布作者 | admin |
| 发布时间 | 2026-10-05 22:46:08 |
| 下载权限 | 免费下载 |
| 附件数量 | 2 个下载链接 |
| 浏览次数 | 226 |
| 讨论数量 | 0 |
| 主题状态 | 正常讨论中 |