 安全软件
点击放大
VULNaware - Open-source vulnerability prioritization engine th
项目说明
Prioritisation & Awareness Engine
Nowadays, scanners produce thousands of rows. Most of them don't matter right now. was made to
answer one question reliably: which of these findings, on which hosts, need urgent attention today.
---
ingests exports from scanners, enriches them against public threat-intel
feeds, and computes a priority score — then gets the findings that
actually matter in front of the right people: SOC alerts, email notifications, and ITSM tickets.
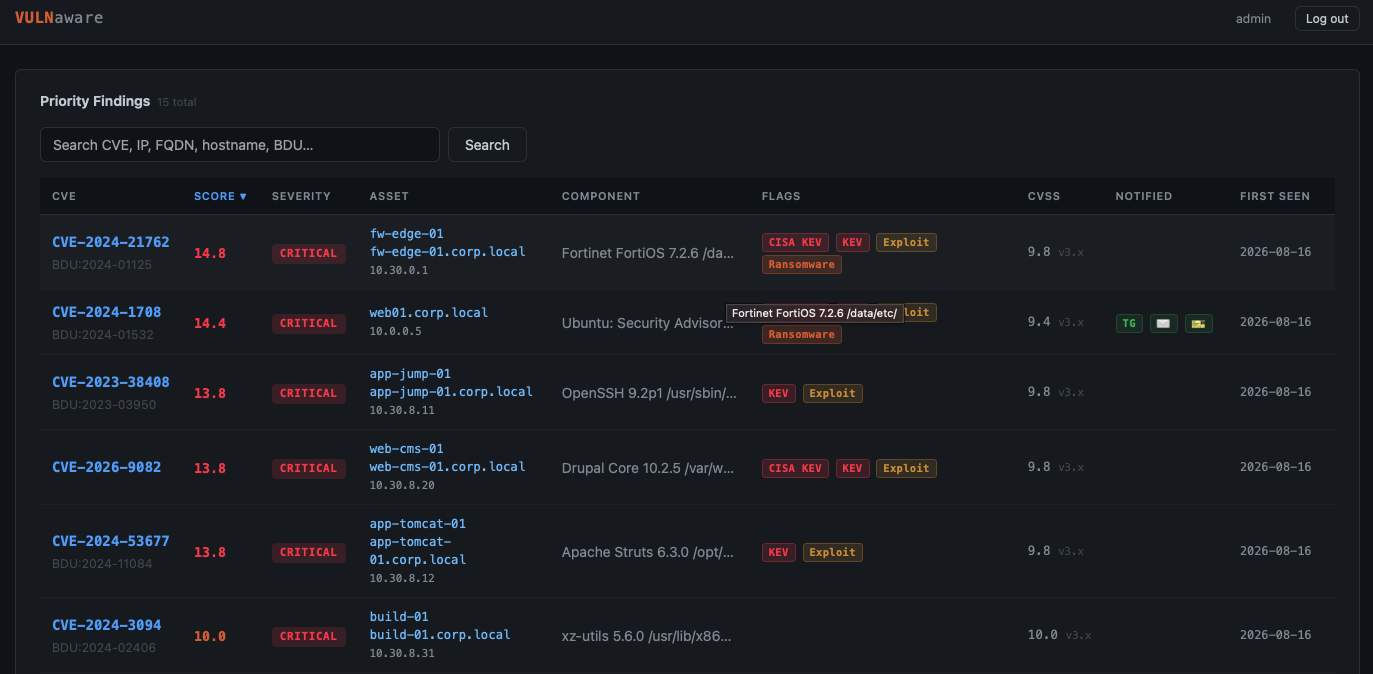
!dashboard
---
Key features
1. Popular scanners integration
Protected en and attack surface should be taken into account
during prioritisation.
Most critical should be prioritised on the most
critical hosts from the attacker's perspective. This is often hosts located in the DMZ and internet-facing services.
extracts host from scanners via an API,
based on specific criteria configured on the scanner side.
| Vuln Scanner | Criteria |
|---------------------|----------------------------------|
| Nessus Pro | Name of the scanning task |
| Greenbone/OpenVAS | Name of the tag assigned to host |
| MaxPatrol VM | Number of group contaning hosts |
Scanner ingestion is made from four source-specific drop folders, each watched on its own schedule tick:
- MaxPatrol VM CSV (/Maxpatrol/, semicolon-delimited, comma-decimal
CVSS, newline-joined vuln IDs is hand-copied, or freshly pulled straight from the MaxPatrol VM REST API).
- Nessus Pro CSV (/Nessus//, one file per scan is hand-copied, or
pulled from the Nessus REST API.
- Greenbone/OpenVAS CSV (/Greenbone//, one file per scan task is hand-copied, or pulled over GMP
from a tagged host scope and enriched with host FQDN/OS; a single row's comma-separated CVEs
cell expands into one finding per CVE).
- Custom-CSV importer (/custom_cs/, hand-copied). One row per CVE,
deduplicated, with an import gate ( + at least one of ip/hostname/fqdn, or the row is
skipped).
!scanners
2. Best community feeds
Threat-intel enrichment from:
MaxPatrol VM CS's
trend column, so it is simply absent (and unscored) for other scanners.
!feeds
3. prioritisation
Deterministic prioritization:
1. with se below the limit are excluded from the scope.
2. KE/exploit tags are added on top and prioritized. CISA KEV has higher priority
than KEV.
Prioritization means notification and ticket creation in ITSM.
NOTE: Some exist without a C but might have some national
ID assigned. Such an example is the FSTEC BDU ID. Such are
prioritised differently; see BDU-keyed findings.
!prioritisation
4. Realtime urgent notifications
During the process of prioritisation, notifications can be sent by two channels:
You get notifications straight on your phone.
You can hide asset information like hostname and IP address from
by changing the setting
hide_assets to true in the /config.yaml file.Each finding is notified once. You can also send it manually through the web interface.
!email and
5. ITSM integration
After notification, a ticket is created in ITSM:
!jira_sm
6. Simple web application to track
Web application is a searchable findings table, and a
per-finding card with an audit trail and four actions: notify by
host ticket to ITSM, or delete the finding.
See working with the dashboard.
!
!
7. Auto or manual modes
You can prioritise in auto or manual dispatch.
By configuring the mode setting in the /config.yaml file,
you decide whether the worker sends notifications and tickets on its own,
or whether an analyst reviews the ranked queue and dispatches from the web app
by hand. Scoring runs the same either way.
---
Architecture
!architecture
A single :latest Docker image serves Web app & Scheduler(worker).
| Container | Role |
|---|------------------------------------------------------|
| postgres | PostgreSQL 17 |
| app | Web dashboard, terminates TLS on 443, loopback-bound |
| worker | APScheduler — runs ingestion / feeds / prioritisation / notify / ITSM on schedule |
Tech stack
Python 3.13 · PostgreSQL 17 · SQLAlchemy 2 + Alembic · Flask + Jinja2 · APScheduler ·
argon2-cffi · pandas · requests (MaxPatrol VM / Nessus APIs) · python-g GMP) ·
Docker / docker-compose.
---
Getting started
---
Configuration
settings come from two files, both managed through run_config.py:
| Console command | Writes to | Contains |
|---|---|---|
| set <key> <value> | /config.yaml | E except auth info — mounted read-only into containers |
| set_secret <key> | .env (chmod 600, gitignored) | Passwords, tokens, API keys, and usernames |
| db init / add_user | PostgreSQL | Schema migrations / dashboard login rows |
Run settings [section] in the console at any time to list every configurable key.
save command persists all staged changes and also scaffolds every known secret into .env as an emptyNAME="" placeholder, so the file always shows the complete list of configurable secrets
e they're set. Note: a console save rewrites config.yaml via yaml.dump,
which drops hand-written comments from the shipped file — keep a copy if you rely on them.
If postgres sits on an internal-only Docker network, unreachable from the host
then run run_config.py in Docker deployments: **set / set_secret / save
on the host; db init / db check / add_user in the container**.
Use command below to run run_config.py in the container.
Full options reference
Every configurable key, grouped by section, lives in docs/options.md —
default, storage location (config.yaml vs .env), and description for all
settings.
---
MaxPatrol VM API export
can pull data from the MaxPatrol VM REST API on every scanner-import tick,
It's opt-in and off by default:
docs/source_mpvm.md walks through the MaxPatrol side: creating the
asset group that scopes the export, finding its group_id, and the API account.
Nessus API export
can export every scan located in a configured Nessus folder directly from
the Nessus REST API on every scanner-import tick.
scans_folder(configured in Nessus) is required whenever scanner.nessus.api.enabled is true — an empty value
is a configuration error, never "export the whole appliance".
It accepts either the folder's display name (as shown in the UI) or its numeric id.
docs/source_nessus.md walks through the Nessus side: organising scans
into a folder, generating the API key pair, and what C rows mean for this source (there is
no manual_review bucket here — see the doc for why).
Greenbone/Open
can pull every task's latest report directly over GMP (Greenbone Management Protocol)
on every scanner-import tick. GMP is a session protocol — connect, authenticate, issue commands.
scanner.greenbone.api.tag is required whenever the API export is enabled — an empty value ne "export
every host on the appliance". It names a tag you assign to host assets in the Greenbone UI
(Assets → Hosts).
The transport is SSH, not TLS. Greenbone's own gvmd process is
bound to a Unix socket only (/run/gvmd/gvmd.sock) — there is no GMP TCP port to connect to. It's
reached through an SSH endpoint whose forced command bridges every login to that socket viasocat:
Which is why there are two independent credential pairs — G/G
log into the SSH bridge, G/G authenticate the GMP session once
connected.
docs/source_greenbone.md walks through the Greenbone side: tagging
the hosts you want monitored, setting up the SSH bridge and GMP account.
Custom CS
can import every scan from custom CSV file on every scanner-import tick.
docs/source_custom_csv.md walks through the
custom CS process.
Example source files
ships three sanitized example exports, so you can prove the pipeline
works during deployment — before any real scanner data exists. They use reser
addresses (192.11.224.x, 10.0.0.x) and placeholder hosts (Hostname1, example.com,corp.local); no real asset data is in the repo.
| File | Rows | What it exercises |
|---|---|---|
| /Maxpatrol.csv | 6 | The full 15-column export: multi-line quoted cells, comma-decimal CVSS (8,8), multi-id blocks (CVE + BDU + CWE + GHSA + PT), and a C high row |
| /Nessus/example_csv.csv | 4 | A multi-CVE row, a Low-se row (out of scope on the default eligible_se), a C informational plugin (dropped), and the host-enrichment columns (Host IP/Host FQDN/Host OS) an API-dri carries |
| /Greenbone/example_csv.csv | 4 | Two multi-C rows (one an 8-C), a Low-se row with a real port (tcp/22), a C ad row (dropped), and the Host FQDN/Host OS enrichment columns an API-dri carries |
Feed downloads (CISA KE NVD2/KE BDU)
CISA KE no token — it is a public JSON catalog fetched with a single GET and cached to//cisa_ke.json, re-parsed only when the file hash changes.
KEV and NVD2 download themselves via the v3 backup API by default
(GET /backup/<index> → pre-signed ZIP URL → extract).
FSTEC BDU loads the CIRCL-curated Parquet dataset from HuggingFace via the datasets library.
Each feed gets its own folder under //:
Set feeds..download: false / feeds..download: false to fall
back to reading an already-downloaded local file/directory instead (air-gapped operation);
likewise, an empty feeds.fstec_bdu.hf_dataset falls back to a direct CSV/JSON/JSONL URL.
A 402/403 (no entitlement for that index) or a missing token skips the feed for
that run rather than triggering a stale-feed HOLD.
Feed health states (feed_state.status, via run_config.py):
| Status | Meaning | HOLD? |
|---|---|---|
| ok | Parsed and upserted normally | No |
| skipped | Config gap or no entitlement — nothing was fetched | No |
| degraded | Fetched fine, but the upstream returned an empty catalog | No |
| error | The run raised — download, parse or database failure | Yes |
degraded is the case worth understanding. An upstream can answer with valid JSON and zero
entries — a partial deploy, a CDN error page, a schema change. Nothing raises, so this used
to record a clean success. Your existing data keeps working and keeps scoring (feed upserts
ne), which is why it does not trigger a HOLD; but last_success_at is not
ad and an ops health alert (feed_degraded) fires, because a feed that has silently
stopped updating should not look healthy. The stored file hash is deliberately not ad
either, so the next run re-parses instead of skipping on an unchanged-file check.
Retrying a failed feed. A feed left error/ne (or is_stale) retries everyfeeds.retry_minutes (default 30) rather than waiting out its full cadence_hours — and is
force-retried immediately on every worker container restart, regardless of how recently it last tried.degraded and skipped do not get this fast retry: neither will fix itself sooner, and
for / a retry re-downloads the entire backup archi
of MB), so retrying a broken upstream every 30 minutes instead of every cadence_hours would
just multiply the wasted bandwidth.
Notifications (
Enable channels in config.yaml (notifications. /notifications.email.enabled); the credentials for both are secrets. See
docs/email_notify.md for SMTP setup, recipient lists and
the digest.
ITSM Integration
creates one host-ticket per asset, carrying its actionable findings. itsm: inconfig.yaml has one sub-block per supported platform
(jira, osTicket, GLPI, znuny) — exactly oneitsm.<platform>.enabled may be true at a time; the one that is decides where tickets go.
Enabling more than one is refused rather than guessed at, with a health alert.
Jira is one of several supported ITSM platforms — see documents below for other ITSM support.
| Part of the request | What sets |
|----------------------------------------|------------------------------------------|
| docs/itsm_jira.md | Covers the Jira Service Management setup |
| docs/itsm_glpi.md | Covers the GLPI setup |
| docs/itsm_osticket.md | Covers the osTicket setup |
|docs/itsm_znuny.md | Covers the Znuny setup |
Outbound proxy (HTTP / SOCKS)
If the host reaches the Internet through a corporate proxy, point at it with
one shared endpoint and switch it on per traffic category — each toggle is independent:
proxy.feeds.enabled — feed downloads (CISA KE KEV/NVD2, FSTEC BDUincl. the HuggingFace path)
proxy. — proxy.itsm.enabled — ITSM API calls, whiche is active (SaaS outside the local network)Supported schemes: http://, socks4://, socks5://, and socks5h:// (likesocks5 but DNS is resolved by the proxy — use this when the host cannot resolve
external names itself). Authentication is optional; credentials are secrets and live in.env, never in config.yaml or inside the URL (the console rejects forms):
SOCKS support uses the PySocks package (in requirements.txt); HTTP proxies need no
extra dependency. E not covered by an enabled toggle keeps connecting
directly — the dashboard, PostgreSQL, the MaxPatrol and Greenbone APIs are internal and are ne.
---
Deployment smoke test
The MaxPatrol example is the one to use — see the caveat below for why it is the only file that
reaches
Then check, in order: the finding appears on the dashboard, a card arrives on
the email digest, and a Jira request is created. That single pass exercises ingestion,
prioritisation and both outbound integrations.
Expect 1 stored finding from 6 rows. That is the pipeline working, not data loss: four rows
are low/medium and fall outside the default prioritisation.eligible_se
(critical, high), and one high row carries no CVE — C rows are only kept atcritical. What survives is C (high, CVSS 9.1).
> Only the MaxPatrol example can trigger notifications and tickets. Its row is
> flagged trend=true *and* comes from the MaxPatrol importer, so it earns the trending signal
> that the notify/ticket gate requires.
---
Scheduling — when the engine runs what
The worker container runs an APScheduler instance that owns every recurring action. Nothing
is e: dropping a CSV in import folder does not trigger an import, it waits for the next tick.
See docs/scheduling.md for more information about scheduling and
how it designed.
---
Documentation Reference
| Doc | What's in it |
|---|-------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------|
| docs/options.md | Full settings reference — every config.yaml / .env key, default, and description, grouped by section. |
| docs/source_mpvm.md | Setting up MaxPatrol VM as a source — the asset group that scopes the export, its group_id, the API account, and the manual-CS. |
| docs/source_nessus.md | Setting up Nessus as a source — the scan folder that scopes the export, the API key pair, host enrichment, and what "no CVE" means for this source (no manual_review bucket). |
| docs/source_greenbone.md | Setting up Greenbone / OpenVAS as a source — the GMP-o session model, the API export vs. the manual GSA CSV, and the shared drop folder both end in. |
| docs/greenbone_setup/setup_greenbone.md | Standing up Greenbone Community Edition itself — the official Docker Compose stack plus the separate SSH endpoint python-gvm connects through. |
| docs/source_custom_csv.md | Importing from a plain CSV — the canonical lowercase header names, which columns are required, and the drop folder the importer watches. |
| docs/BDU_keyed_findings.md | MaxPatrol VM rows that carry an FSTEC BDU: id instead of a CVE — the manual_review table, and the two ways they beha from C. |
| docs/email_notify.md | Configuring email notifications — SMTP host/port/TLS, credentials, SOC vs. ops recipient lists, and troubleshooting. |
| docs/itsm_jira.md | Configuring Jira Service Management so 's host-tickets land — API token, service desk permissions, request type and priority prerequisites, dedup behaviour. |
| docs/itsm_glpi.md | Configuring GLPI so 's host-tickets land — enabling the v2 REST API, the OAuth2 client, TLS trust, and the one-ticket-per-asset grouping. |
| docs/itsm_osticket.md | Configuring osTicket so 's host-tickets land — API key and its source-IP binding, submitter identity, and why a host's ticket is ne after it is created. |
| docs/itsm_znuny.md | Configuring Znuny so 's host-tickets land — importing the GenericInterface web service, matching its name to itsm.znuny.webservice, the agent account and TLS trust. |
| docs/dashboard.md | Working with the dashboard. |
| docs/ssh_tunnel.md | Reaching the loopback-bound dashboard from a workstation over an SSH tunnel — port forward, certificate trust, persistent config, hardening. |
| docs/scheduling.md | What the worker runs and how often — each job's interval and the setting behind it, the run-once-on-worker-start behaviour, and how to change the cadence. |
| docs/docker_dns.md | Making a LAN-only hostname resolve from inside the app / worker containers via extra_hosts — the fix for name-resolution failures against a scanner, SMTP relay or ITSM host. |
项目信息
开发语言:Python
Star 数:35
技术要点
该项目属于安全软件方向的开源资源,代码结构清晰,适合安全研究人员学习参考。项目围绕Open-source vulnerability prioritization engine that enriches scanner findings with vulnerability intelligence, identifies urgent risks, and automates alerts and ITSM ticketing.展开,提供了可运行的实现,对理解相关安全机制、工具原理与攻防技术具有较高的研究价值。
从技术实现角度看,此类项目的核心在于对底层原理的深入理解与工程化落地。开发者在研究过程中可以结合官方文档与社区讨论,梳理项目的初始化流程、核心模块职责与数据流转,逐步掌握其中的技术细节与设计思路。
使用与学习建议
1. 下载源码压缩包,解压到本地环境。
2. 根据项目类型准备对应的运行环境与依赖。
3. 按照 README 中的步骤完成配置与部署。
4. 在隔离的测试环境中运行验证,避免影响生产系统。
免责声明
本资源来源于开源社区,仅供安全研究、技术学习与合法授权范围内的攻防演练使用,请勿用于任何非法或侵害他人权益的用途。使用本项目产生的一切后果由使用者自行承担。
| 资源标题 | VULNaware - Open-source vulnerability prioritization engine th |
| 所属分类 | 安全软件 |
| 发布作者 | admin |
| 发布时间 | 2026-10-05 22:49:03 |
| 下载权限 | 免费下载 |
| 附件数量 | 2 个下载链接 |
| 浏览次数 | 222 |
| 讨论数量 | 0 |
| 主题状态 | 正常讨论中 |