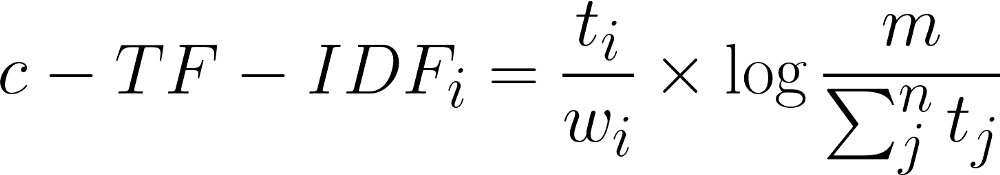 CTF思路
点击放大
项目说明
![PyPI - Python]()
![PyPI - License]()
<img src="images/ctfidf.png" width="35%" height="35%" align="right" />
c-TF-IDF
c-TF-IDF is a class-based TF-IDF procedure that can be used to generate features from textual documents based
on the class they are in.
Typical applications:
* Informati per Class: Which words make a class stand-out compared to all others?
* Class Reduction: Using c-TF-IDF to reduce the number of classes
* Semi-supervised Modeling: Predicting the class of unseen documents using only cosine similarity and c-TF-IDF
Corresponding TowardsDataScience post can be found here.
<a name="toc"/></a>
Table of Contents
<!--ts-->
1. About the Project
2. Getting Started
2.1. Requirements
2.2. Basic Usage
2.3. Informati per Class
2.4. Class Reduction
2.5. Semi-supervised Modeling
3. c-TF-IDF
<!--te-->
<a name="gettingstarted"/></a>
2. Getting Started
Back to ToC
<a name="requirements"/></a>
2.1. Requirements
Fortunately, the requirements for this adaption is limited to numpy, scipy, pandas, and scikit-learn.
Basically your normal data stack which you can install with:
<a name="usage"/></a>
2.2. Basic Usage
<a name="informative"/></a>
2.3. Informati per Class
What makes c-TF-IDF unique compared to TF-IDF is that we can adopt it such that we can search for words that make up certain classes.
If we were to have a class that is marked as space, then we would expect to find space-related words, right?
To do this, we simply extract the c-TF-IDF matrix and find the highest in each class:
Now that we ha the words per class, we can inspect the results:
To me, it clearly shows words related to the category sci.space!
<a name="reduction"/></a>
2.4. Class Reduction
At times, having many classes can be detrimental to clear analyses. You might want a more general o to get a feeling of the major classes in the data.
Fortunately, we can use c-TF-IDF to reduce the number of classes to whate you are looking for.
We can do this by comparing the c-TF-IDF of all classes with each other in order to merge the most similar classes:
The result shows which categories are most similar to each other and therefore which could be merged:
This definitely seems to make sense! Combining christian with atheism and pc hardware with mac hardware.
<a name="modeling"/></a>
2.5. Semi-supervised Modeling
Using c-TF-IDF we can e semi-supervised modeling directly without the need for a predicti.
We start by creating a c-TF-IDF matrix for the train data. The result is a per class which should represent the content of that class. Finally, we check, for pre unseen data, how similar that is to that of all categories:
The results can be extracted with a simple classification report in scikit-learn:
Although we can see that the results are nothing to write home about with an accuracy of roughly 50%… The accuracy is much better than randomly guessing the class which is 5%.
Without any complex predicti, we managed to get decent accuracy with a fast and relatively simple model. We did not e the data!
<a name="ctfidf"/></a>
3. c-TF-IDF
Back to ToC
The goal of the class-based TF-IDF is to supply all documents within a single class with the same class .
In order to do so, we have to start looking at TF-IDF from a class-based point of view instead of indi documents.
If documents are not indi, but part of a larger collective, then it might be interesting to actually
regard them as such by joining all documents in a class together.
The result would be a very long document that is by itself not actually readable. Imagine reading a document consisting of 10 000 pages!
However, this allows us to start looking at TF-IDF from a class-based perspective.
Then, instead of applying TF-IDF to the newly created long documents, we have to take into account that TF-IDF will take the number of classes instead of the number of documents since we merged documents.
All these changes to TF-IDF results in the following formula:
<img src="images/ctfidf.png" width="50%" height="50%" align="center" />
Where the frequency of each word t is extracted for each class i and divided by the total number of words w.
This action can be seen as a form of regularization of frequent words in the class.
Next, the total, unjoined, number of documents m is divided by the total frequency of word t across all classes n.
项目信息
开发语言:Python
Star 数:92
技术要点
该项目属于CTF思路方向的开源资源,代码结构清晰,适合安全研究人员学习参考。项目围绕Creating class-based TF-IDF matrices展开,提供了可运行的实现,对理解相关安全机制、工具原理与攻防技术具有较高的研究价值。
从技术实现角度看,此类项目的核心在于对底层原理的深入理解与工程化落地。开发者在研究过程中可以结合官方文档与社区讨论,梳理项目的初始化流程、核心模块职责与数据流转,逐步掌握其中的技术细节与设计思路。
使用与学习建议
1. 下载源码压缩包,解压到本地环境。
2. 根据项目类型准备对应的运行环境与依赖。
3. 按照 README 中的步骤完成配置与部署。
4. 在隔离的测试环境中运行验证,避免影响生产系统。
免责声明
本资源来源于开源社区,仅供安全研究、技术学习与合法授权范围内的攻防演练使用,请勿用于任何非法或侵害他人权益的用途。使用本项目产生的一切后果由使用者自行承担。
| 资源标题 | cTFIDF - 创建基于类的TF-IDF矩阵 |
| 所属分类 | CTF思路 |
| 发布作者 | admin |
| 发布时间 | 2026-10-05 23:56:13 |
| 下载权限 | 免费下载 |
| 附件数量 | 2 个下载链接 |
| 浏览次数 | 436 |
| 讨论数量 | 0 |
| 主题状态 | 正常讨论中 |