 漏洞知识库
点击放大
Krawl - Krawl is a customizable, lightweight, cloud-native
项目说明
<h1 align="center">Krawl</h1>
<h3 align="center">
<a name="readme-top"></a>
<img
src="img/krawl-svg.svg"
height="250"
>
</h3>
<di="center">
<p align="center">
A modern, customizable web honeypot ser to detect and track malicious activity from attackers and web crawlers through deceptive web pages, fake credentials, and canary tokens.
</p>
<di="center">
<a href="
<img src=" alt="License">
</a>
<a href="
<img src=" alt="Release">
</a>
</div>
<di="center">
<a href="
<img src=" alt="GitHub Container Registry">
</a>
<a href="
<img src=" alt="Kubernetes">
</a>
<a href="
<img src=" alt="Helm Chart">
</a>
</div>
</div>
Table of Contents
- Docker Run
- Docker Compose
- Kubernetes
- U (Python)
- config.yaml
- En
Demo
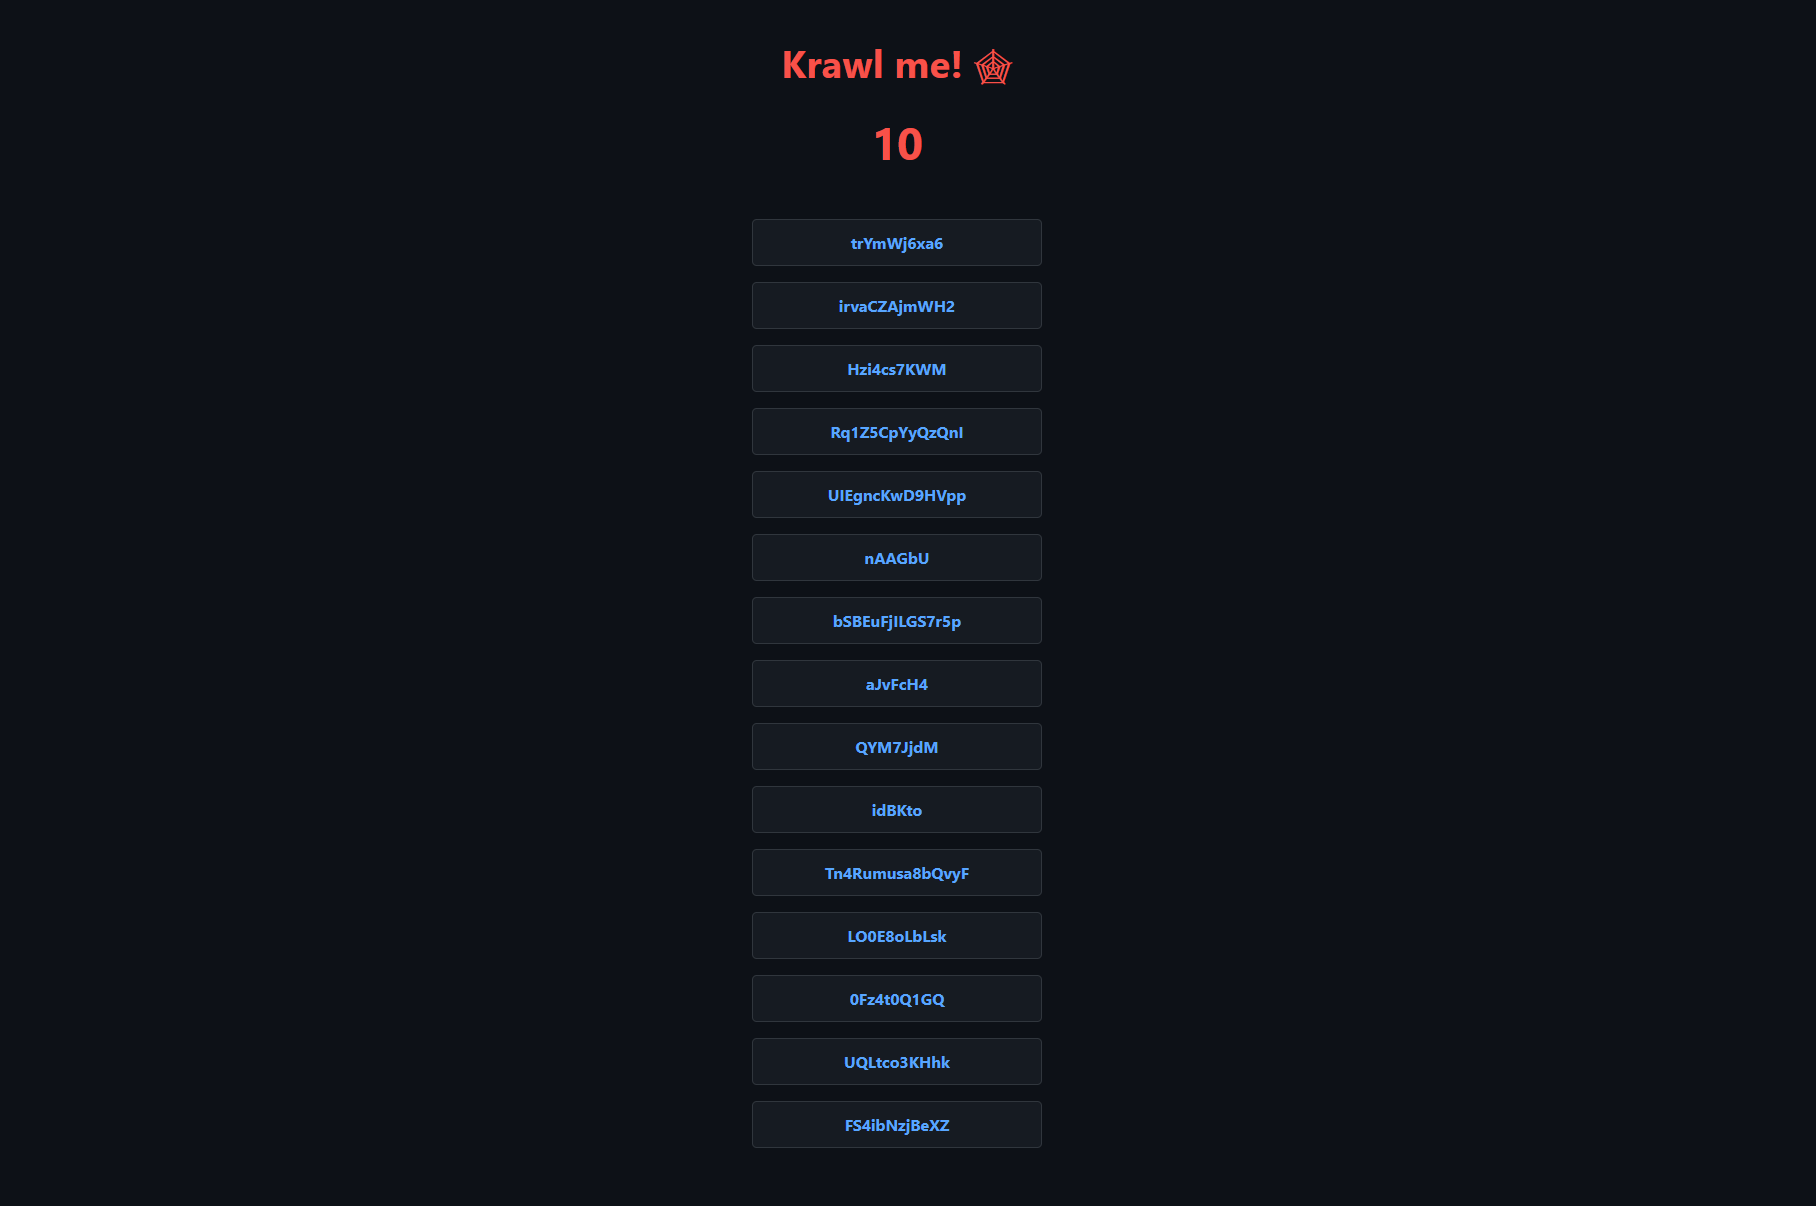
Tip: crawl the
robots.txt paths for additional funKrawl URL:
View the dashboard
What is Krawl?
Krawl is a cloud‑nati ser to detect, delay, and analyze malicious attackers, web crawlers and automated scanners.
It creates realistic fake web applications filled with low‑hanging fruit such as admin panels, configuration files, and exposed fake credentials to attract and identify suspicious activity.
!dashboard
By wasting attacker resources, Krawl helps clearly distinguish malicious behavior from legitimate crawlers.
It features:
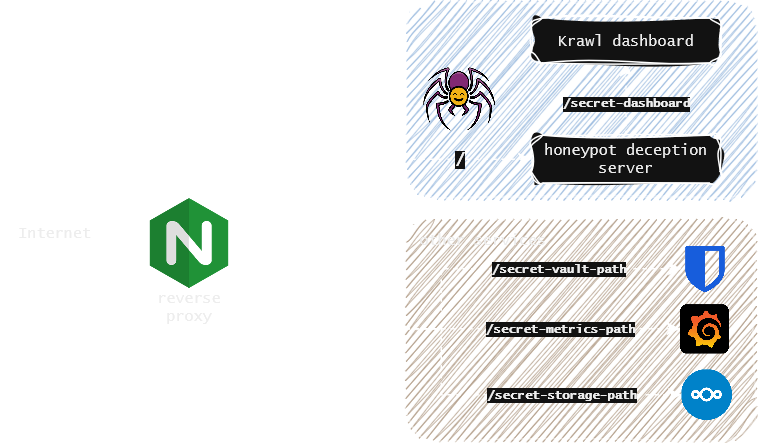
You can easily expose Krawl alongside your other services to shield them from web crawlers and malicious users using a reverse proxy. For more details, see the Reverse Proxy documentation.
!use case
Krawl Dashboard
Krawl provides a comprehensi, accessible at a random secret path generated at startup or at a custom path configured via KRAWL_DASHBOARD_SECRET_PATH. This keeps the dashboard hidden from attackers scanning your honeypot.
The dashboard is organized in six tabs:
!geoip
!attack_types
!ipinsight
Additionally, after authenticating with the dashboard password, protected tabs become a:
The header icons open the API docs, the banlist export, and a settings panel showing the running configuration and a maintenance page for running scheduled tasks on demand.
For more details, see the Dashboard documentation.
Deployment Modes
Krawl supports two deployment modes, controlled by the mode setting in config.yaml or the KRAWL_MODE en .
| | Standalone | Scalable |
|---|---|---|
| Database | SQLite (WAL mode) | PostgreSQL |
| Cache | In-memory Python dict | Redis (multi-tier TTL) |
| Replicas | 1 (single instance) | 1+ (horizontal scaling) |
| External deps | None | PostgreSQL + Redis |
| Best for | De, <500k requests | Production, HA, >500k requests |
Standalone: ideal for de en or homelabs with low request counts. Zero additional configuration needed, just run Krawl and it works.
Scalable: designed for production en or high-traffic honeypots. The Helm chart defaults to this mode.
For detailed configuration, Docker Compose examples, Kubernetes/Helm setup, and step-by-step migration instructions, see the Deployment Modes documentation.
Krawl Banlist
Krawl maintains a regularly updated banlist.txt of IP addresses from attackers that triggered its honeypot traps. The banlist is published weekly and a for download, helping the community preemptively block known malicious actors e using Krawl.
The banlist can also be fetched directly from:
Sharing banlists between instances
Krawl instances can federate their banlists: each one can publish its own list on an
unauthenticated path and pull in lists from other instances (or any plain-text IP list).
Fetched IPs are merged into the local ban decisions and shown in the dashboard.
Quickstart
Docker Run
Run Krawl in standalone mode with the latest image:
Access the server at
Docker Compose
Create a docker-compose.yaml with one of the two deployment modes.
Standalone: just Krawl server with Sqlite storage:
Scalable: with PostgreSQL and Redis:
> [!CAUTION]
> The example below uses default passwords (krawl/krawl). Change them before deploying to production.
To deploy, just run
Production-ready compose files are also a in the docker/ directory. For de (builds from source with hot-reload), use the compose files in docker/dev/.
For more details on both modes, see Deployment Modes.
Kubernetes
Krawl is also a natively on Kubernetes. Installation can be done either or using the Helm chart.
The Helm chart defaults to scalable mode with bundled PostgreSQL and Redis:
Minimal example files are provided for both modes:
.yaml ---> Scalable (default).yaml ---> StandaloneSee Deployment Modes and Chart documentation for full configuration and migration instructions.
U (Python)
Run Krawl directly with Python 3.13+ and u for local de or testing:
Access the server at
Configuration
Krawl uses a configuration hierarchy in which en take precedence over the configuration file. This approach is recommended for Docker deployments and quick out-of-the-box customization.
Configuration .yaml
You can use the config.yaml file for ad configurations, such as Docker Compose or Helm chart deployments.
Configuration
All settings can be supplied as en , which o config.yaml.
The name is KRAWL_ plus the setting path in upper case, so dashboard.password
becomes KRAWL_DASHBOARD_PASSWORD.
<details>
<summary><b>Server and link generation</b> (11 )</summary>
How Krawl presents itself and shapes the maze of generated pages.
| En | Description | Default |
|----------------------|-------------|---------|
| CONFIG_LOCATION | Path to yaml config file | config.yaml |
| KRAWL_PORT | Ser port | 5000 |
| KRAWL_DELAY | Response delay in milliseconds | 100 |
| KRAWL_SER | HTTP Ser for deception | "" |
| KRAWL_LINKS_LENGTH_RANGE | Link length range as min,max | 5,15 |
| KRAWL_LINKS_PER_PAGE_RANGE | Links per page as min,max | 10,15 |
| KRAWL_CHAR_SPACE | Characters used for link generation | abcdefgh... |
| KRAWL_MAX_COUNTER | Initial counter value | 10 |
| KRAWL_PROBABILITY_ERROR_CODES | Error response probability (0-100%) | 0 |
| KRAWL_INFINITE_PAGES_FOR_MALICIOUS | Ser pages to malicious IPs | true |
| KRAWL_MAX_PAGES_LIMIT | Maximum page limit for crawlers | 250 |
| KRAWL_BAN_DURATION_SECONDS | Ban duration in seconds for rate-limited IPs | 600 |
</details>
<details>
<summary><b>Dashboard, metrics and logging</b> (13 )</summary>
Dashboard access, cache warmup, Prometheus and log level.
| En | Description | Default |
|----------------------|-------------|---------|
| KRAWL_DASHBOARD_SECRET_PATH | Custom dashboard path | Auto-generated |
| KRAWL_DASHBOARD_PASSWORD | Password for protected dashboard panels | Auto-generated |
| KRAWL_DASHBOARD_CACHE_WARMUP | Pre-compute dashboard data every 5 minutes for instant page loads | true |
| KRAWL_DASHBOARD_WARMUP_PAGES | Number of pages to pre-warm per table panel | 10 |
| KRAWL_DASHBOARD_WARMUP_AGGREGATION | Pre-compute full top_paths/top_ua aggregations for zero-query serving | false |
| KRAWL_DASHBOARD_TOP_N_MIN_COUNT | Minimum access count for top paths/user agents panels (set to 1 to disable) | 5 |
| KRAWL_DASHBOARD_BRAND_NAME | Name in the dashboard wordmark and heading | Krawl |
| KRAWL_DASHBOARD_BRAND_URL | Where the wordmark links (empty renders it as plain text) | Krawl's repository |
| KRAWL_DASHBOARD_BRAND_LOGO | Image URL shown instead of the GitHub mark | Unset |
| KRAWL_DASHBOARD_BRAND_SHOW_ | Show the next to the name | true |
| KRAWL_DASHBOARD_BRAND_CONTACT | Contact shown under the wordmark (address, URL, or plain text) | Unset |
| KRAWL_METRICS_ENABLED | Expose Prometheus metrics at /<dashboard_path>/metrics | true |
| KRAWL_LOG_LEVEL | Application log level (DEBUG, INFO, WARNING, ERROR) | INFO |
</details>
<details>
<summary><b>Database, retention and backups</b> (12 )</summary>
Storage location, how long data is kept, and the dump job.
| En | Description | Default |
|----------------------|-------------|---------|
| KRAWL_DATABASE_PATH | Database file location | data/krawl.db |
| KRAWL_DATABASE_PERSIST_SUSPICIOUS_ONLY | Only persist suspicious requests to the access log | false |
| KRAWL_MAP_TILE_URL | Tile URL template for the dashboard map ({z}/{x}/{y}, optional {s}/{r}) | Esri dark canvas |
| KRAWL_MAP_TILE_ATTRIBUTION | Attribution shown on the map | Esri/OSM |
| KRAWL_MAP_API_KEY | Appended to every tile request as a query parameter — required by CARTO | _(empty)_ |
| KRAWL_MAP_API_KEY_PARAM | Name of that query parameter (api_key, apikey, key) | api_key |
| KRAWL_IP | Drop IPv6 requests entirely: still logged to stdout, ne, ban-checked or exported | false |
| KRAWL_IP | Also delete existing IPv6 rows at the next startup (irre; requires KRAWL_IP) | false |
| KRAWL_DATABASE_RETENTION_DAYS | Days to retain data in database | 30 |
| KRAWL_BACKUPS_PATH | Path where database dump are saved | backups |
| KRAWL_BACKUPS_CRON | cron expression to control backup job schedule | */30 * * * * |
| KRAWL_BACKUPS_ENABLED | Boolean to enable db dump job | true |
</details>
<details>
<summary><b>Traps: tarpit, deception pages and canary</b> (6 )</summary>
Opt-in traps and the pages served to attackers.
| En | Description | Default |
|----------------------|-------------|---------|
| KRAWL_TARPIT_ENABLED | Trap AI agents with slow responses and random text | false |
| KRAWL_TARPIT_DELAY_SECONDS | Extra delay in seconds added per response when tarpit is active | 5 |
| KRAWL_DECEPTION_IMPORT_PAGES | Auto-import deception pages from src/templates/deception/ at startup | true |
| KRAWL_CUSTOM_TEMPLATE_PATH | Path inside the container to a custom HTML template. Template must include {counter} and {content} placeholders. | /templates/custom_page.html |
| KRAWL_CANARY_TOKEN_URL | External canary token URL | None |
| KRAWL_CANARY_TOKEN_TRIES | Requests before showing canary token | 10 |
</details>
<details>
<summary><b>IP reputation analyzer</b> (6 )</summary>
Thresholds that decide how an IP gets classified.
| En | Description | Default |
|----------------------|-------------|---------|
| KRAWL_HTTP_RISKY_METHODS_THRESHOLD | Threshold for risky HTTP methods detection | 0.1 |
| KRAWL_D | Threshold for robots.txt | 0.1 |
| KRAWL_UNEHOLD | Coefficient of threshold for timing | 0.5 |
| KRAWL_UNEWINDOW_SECONDS | Time window for request timing analysis in seconds | 300 |
| KRAWL_USER_AGENTS_USED_THRESHOLD | Threshold for detecting multiple user agents | 2 |
| KRAWL_ATTACK_URLS_THRESHOLD | Threshold for attack URL detection | 1 |
</details>
<details>
<summary><b>Threat-intel capture</b> (4 )</summary>
Fuzzy-hash captured payloads (files and flagged request bodies) and group
near-duplicate into campaign clusters. Requires py-tlsh.
Hashing runs as the scheduled hash-payloads background task (seesrc/tasks/hash_payloads.py), which hashes each captured attack once — new
hits at ingest time, and a one-time backward sweep of existing history
tracked by a payload_hash_watermark high-water mark — then clusters the
digests into recurring-pattern campaigns.
| En | Description | Default |
|----------------------|-------------|---------|
| KRAWL_TLSH_ENABLED | Hash uploaded files and flagged request bodies with TLSH for near-duplicate clustering | true |
| KRAWL_TLSH_CLUSTER_THRESHOLD | TLSH distance below which a payload joins an existing campaign (0 = identical bytes; of a webshell typically diff < 100) | 150 |
| KRAWL_TLSH_CAMPAIGN_MIN_EVENTS | Times a payload must be seen before its campaign appears in the Threats tab | 10 |
| KRAWL_REFERER_ENABLED | Record the inbound HTTP Referer on access logs, for bait-chain tracking | true |
</details>
<details>
<summary><b>Banlist and ignored IPs</b> (4 )</summary>
Sharing banlists with other instances, and traffic to ne.
| En | Description | Default |
|----------------------|-------------|---------|
| KRAWL_IGNORED_IPS | Comma-separated IPs/CIDRs ne, banned or exported | Loopback, RFC1918, link-local, CGNAT |
| KRAWL_BANLIST_EXPORT_PATH | Public banlist download path, e.g. /public_banlist.txt (empty = disabled) | "" |
| KRAWL_BANLIST_SOURCES | Comma-separated upstream banlist URLs to fetch and merge | Krawl community banlist |
| KRAWL_BANLIST_REFRESH_INTERVAL | Seconds between upstream banlist fetches | 3600 |
</details>
<details>
<summary><b>AI-generated deception pages</b> (10 )</summary>
See the AI Generation documentation.
| En | Description | Default |
|----------------------|-------------|---------|
| KRAWL_AI_ENABLED | Enable AI-generated deception pages | false |
| KRAWL_AI_PROVIDER | AI provider ("openrouter" or "openai") | "openrouter" |
| KRAWL_AI_OPENAI_BASE_URL | Optional OpenAI Base URL for custom API endpoints | " |
| KRAWL_AI_API_KEY | API key for AI provider | None |
| KRAWL_AI_MODEL | AI model to use for page generation | "nvidia/nemotron-3-super-120b-a12b:free" |
| KRAWL_AI_TIMEOUT | Request timeout in seconds for AI API calls | 60 |
| KRAWL_AI_MAX_DAILY_REQUESTS | Max number of AI-generated pages per day (0 = unlimited) | 0 |
| KRAWL_AI_PROMPT | Custom prompt template for AI page generation | Default prompt |
| KRAWL_AI_REASONING_ENABLED | Enable reasoning tokens (OpenRouter reasoning models only) | false |
| KRAWL_AI_REASONING_EFFORT | Reasoning effort (none, minimal, low, medium, high, xhigh) | "medium" |
</details>
<details>
<summary><b>Scalable mode: PostgreSQL and Redis</b> (13 )</summary>
Only used when KRAWL_MODE=scalable. See Deployment Modes.
| En | Description | Default |
|----------------------|-------------|---------|
| KRAWL_MODE | Deployment mode (standalone or scalable) | standalone |
| KRAWL_POSTGRES_HOST | PostgreSQL hostname | localhost |
| KRAWL_POSTGRES_PORT | PostgreSQL port | 5432 |
| KRAWL_POSTGRES_USER | PostgreSQL username | krawl |
| KRAWL_POSTGRES_PASSWORD | PostgreSQL password | krawl |
| KRAWL_POSTGRES_DATABASE | PostgreSQL database name | krawl |
| KRAWL_REDIS_HOST | Redis hostname | localhost |
| KRAWL_REDIS_PORT | Redis port | 6379 |
| KRAWL_REDIS_DB | Redis database number | 0 |
| KRAWL_REDIS_PASSWORD | Redis password | None |
| KRAWL_REDIS_CACHE_TTL | TTL in seconds for dashboard warmup data | 600 |
| KRAWL_REDIS_HOT_TTL | TTL in seconds for hot-path data (ban info, IP categories) | 30 |
| KRAWL_REDIS_TABLE_TTL | TTL in seconds for paginated dashboard tables | 120 |
</details>
For example
Example of a Docker run with en (standalone mode):
Use Krawl to Ban Malicious IPs
Krawl uses a reputation-based system to classify attacker IP addresses and provides two ways to export IP lists for firewall integration.
The /api/export-ips endpoint queries the database directly and supports filtering by IP category (attacker, bad_crawler, regular_user, good_crawler) and output format (raw, iptables, nftables):
This enables automatic blocking of malicious traffic across platforms:
* OPNsense and pfSense
* RouterOS
* IPtables and Nftables
* Fail2Ban
For full API parameters, examples, and adding custom firewall formats, see the Firewall Exporters documentation.
Krawl can also push banned IPs directly to a Cloudflare Account IP List for use in WAF rules. The sync runs as a background task and updates the list by full replacement on a configurable interval. See the Cloudflare Banlist Sync documentation.
IP Reputation
Krawl uses tasks that analyze recent traffic to build and continuously update an IP reputation score. It runs periodically and e each active IP address based on multiple beha indicators to classify it as an attacker, crawler, or regular user. Thresholds are fully customizable.
!ip reputation
The analysis includes:
Each signal contributes to a weighted scoring model that assigns a reputation category:
attackerbad_crawlergood_crawlerregular_userunknown (for insufficient data)The resulting scores and metrics are stored in the database and used by Krawl to dri, reputation tracking, and automated mitigation actions such as IP banning or firewall integration.
AI-Generated Deception Pages
Krawl can automatically generate realistic deception pages using AI models from OpenRouter or OpenAI APIs. This feature creates unique, plausible honeypot pages on-the-fly to decei without manual page creation.
Key Features:
Quick Setup:
For detailed configuration and usage, see the AI Generation documentation.
You can also contribute deception templates by opening a PR, see Contributing Deception Templates.
Running Behind a Reverse Proxy or CDN
NGINX, Traefik, and other proxies like CloudFlare need header forwarding so Krawl can see the real IP. See the Reverse Proxy documentation for configuration examples and the full header list.
Metrics & Monitoring
Krawl exposes Prometheus metrics at /<dashboard_secret_path>/metrics (enabled by default) and ships with a ready-to-import Grafana dashboard at grafana-dashboard.json.
See the Monitoring documentation for the full metric list, Grafana import steps, and Prometheus / Kubernetes (Ser) scraping setup.
Additional Documentation
| Topic | Description |
|-------|-------------|
| AI Generation | Configure AI-generated deception pages using OpenRouter or OpenAI |
| Deception Pages | Manage, import, and export deception pages; bulk operations and date-based filtering |
| Deployment Modes | Standalone (SQLite) (PostgreSQL + Redis) mode, configuration, and data migration |
| Honeypot | Full o of honeypot pages: fake logins, directory listings, credential files, SQLi/XSS/XXE/command injection traps, and more |
| Dashboard | Access and explore the real-time monitoring dashboard |
| Dashboard API | Krawl's own JSON API: endpoint reference, authentication, interacti docs, and attachment downloads |
| External APIs | Third-party APIs Krawl calls out to for IP data, reputation, and geolocation |
| Reverse Proxy | How to deploy Krawl behind NGINX or use decoy subdomains |
| Database Backups | Enable and configure the automatic database dump job |
| Canary Token | Set up external alert triggers .org |
| Wordlist | Customize fake usernames, passwords, and directory listings |
| Architecture | Technical o of the codebase, request pipeline, database schema, and background tasks |
| Cloudflare Banlist Sync | Pushes banned IPs from Krawl to a Cloudflare Account IP List for use in WAF rules. The sync runs as a background task and updates the list by full replacement. |
| Firewall Exporters | Export IP banlists in raw, iptables, or nftables format via REST API |
| Tarpit | Slow down and poison AI crawlers with delayed, noise-padded responses |
| Metrics & Monitoring | Prometheus metrics endpoint, exposed metrics reference, Grafana dashboard, and Ser scraping |
Contributing
Contributions welcome! Please:
1. Fork the repository
2. Create a feature branch
3. Make your changes
4. Submit a pull request (explain the changes!)
Disclaimer
> [!CAUTION]
> This is a deception/honeypot system. Deploy in isolated en and monitor carefully for security events. Use responsibly and in compliance with applicable laws and regulations.
Star History
<img src=" width="600" alt="Star History Chart" />
项目信息
开发语言:Python
Star 数:773
技术要点
该项目属于漏洞知识库方向的开源资源,代码结构清晰,适合安全研究人员学习参考。项目围绕Krawl is a customizable, lightweight, cloud-native web deception server and anti-crawler that creates fake web applications with low-hanging vulnerabilities using realistic, randomly generated decoy data and AI-generated HTML templates.展开,提供了可运行的实现,对理解相关安全机制、工具原理与攻防技术具有较高的研究价值。
从技术实现角度看,此类项目的核心在于对底层原理的深入理解与工程化落地。开发者在研究过程中可以结合官方文档与社区讨论,梳理项目的初始化流程、核心模块职责与数据流转,逐步掌握其中的技术细节与设计思路。
使用与学习建议
1. 下载源码压缩包,解压到本地环境。
2. 根据项目类型准备对应的运行环境与依赖。
3. 按照 README 中的步骤完成配置与部署。
4. 在隔离的测试环境中运行验证,避免影响生产系统。
免责声明
本资源来源于开源社区,仅供安全研究、技术学习与合法授权范围内的攻防演练使用,请勿用于任何非法或侵害他人权益的用途。使用本项目产生的一切后果由使用者自行承担。
| 资源标题 | Krawl - Krawl is a customizable, lightweight, cloud-native |
| 所属分类 | 漏洞知识库 |
| 发布作者 | admin |
| 发布时间 | 2026-10-06 01:06:37 |
| 下载权限 | 免费下载 |
| 附件数量 | 2 个下载链接 |
| 浏览次数 | 232 |
| 讨论数量 | 0 |
| 主题状态 | 正常讨论中 |